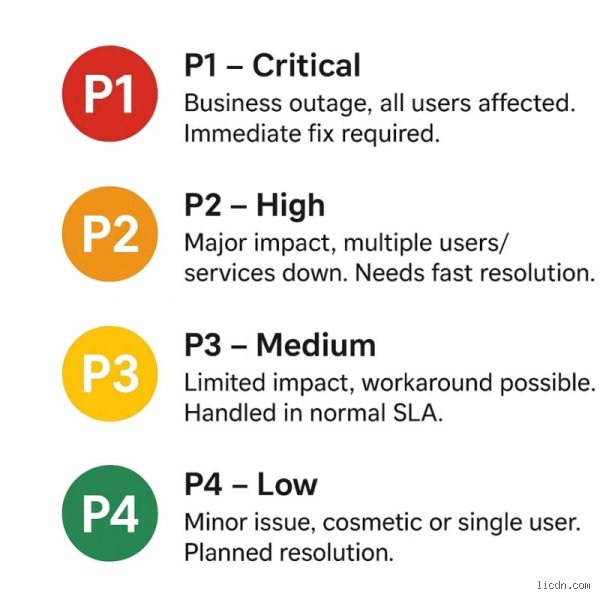
Among these tiers, P1 and P2 stand out as the twin pillars of urgent incident management. They represent the threshold where technical anomalies transform into genuine business emergencies. Understanding the exact definitions, distinctions, operational mechanics, and governance surrounding P1 and P2 priorities is essential for any technical leader, support manager, or engineer looking to build resilient systems and predictable response pipelines.
The foundational anatomy: What do P1 and P2 actually mean?
To understand P1 and P2 priorities, one must first dismantle a common point of operational confusion: the difference between severity and priority. While often used interchangeably in casual conversation, seasoned operations teams treat them as distinct variables.
Severity measures the technical magnitude of an issue, how badly a system, service, or data set is broken from a purely technical standpoint, independent of business context.
Priority measures how urgently the organization must act relative to all other competing work, taking into account business impact, time sensitivity, and operational consequences.
Priority is derived by mapping the incident's impact against its urgency. Within a standard four-tier or five-tier priority matrix (typically ranging from P1 down to P4 or P5), P1 and P2 occupy the apex of urgency.
Priority 1 (P1), Critical
A P1 (Priority 1) incident is an all-hands-on-deck, business-critical emergency. It signifies that a core revenue-generating service, essential operational workflow, or security perimeter has completely failed, affecting a wide user base or an entire organization with no immediate workaround available.
Core Characteristics: Total system outage, widespread user lockouts, active data corruption, catastrophic security breaches, or complete payment gateway failures.
Operational Expectation: Response must be instantaneous (often governed by strict Service Level Agreements demanding acknowledgment within 15 to 30 minutes). Designated responders drop all planned work, assemble immediately, and operate continuously until a resolution or stable workaround is established.
Priority 2 (P2), High
A P2 (Priority 2) incident represents a high-severity disruption that heavily impairs business functions or blocks critical users, but differs from a P1 because the entire organization is not completely paralyzed, or because a viable (even if costly or limited) workaround exists.
Core Characteristics: Severe service degradation, failure of secondary but critical business functions, departmental blockages, or issues impacting high-value clients where alternate paths can temporarily sustain operations.
Operational Expectation: Highly urgent, usually requiring a response within 30 to 60 minutes and resolution targets capped within the same business day (typically 4 to 8 hours). While it commands immediate attention after active P1 items, it does not typically require waking up the entire executive or engineering roster at 3:00 AM unless compounding factors escalate its urgency.
The Impact-Urgency matrix: How P1 and P2 are calculated
Tickets do not magically become P1 or P2 declarations; they are evaluated through a rigid matrix combining Business Impact (how many people or processes are affected) and Urgency (how fast the damage compounds over time).
| Impact Level | High Urgency | Medium Urgency | Low Urgency |
|---|---|---|---|
| High Impact (Enterprise-wide / Revenue-blocking) | P1 (Critical) | P1 / P2 | P2 (High) |
| Medium Impact (Departmental / Key Function) | P2 (High) | P2 / P3 | P3 (Medium) |
| Low Impact (Single User / Inconvenience) | P3 (Medium) | P4 (Low) | P4 (Low) |
As illustrated by the matrix, a P1 designation requires a convergence of high impact and high urgency. If a single employee loses access to their local printer, the impact is low, even if they feel deeply urgent about it; that routes to a low priority. Conversely, if a multi-national retail platform's checkout cart stops processing credit cards on Black Friday, both impact and urgency skyrocket to maximum levels, immediately triggering a P1 major incident protocol.
Why precise P1 and P2 classifications matter
Organizations that fail to strictly define and govern P1 and P2 priorities invariably fall victim to "priority inflation", a phenomenon where every internal user marks their ticket as urgent, rendering the queue meaningless. Establishing ironclad criteria for P1 and P2 brings vital structural benefits:
Elimination of Negotiation Under Pressure: During a live outage, technical teams should not waste valuable minutes arguing about who needs to join the bridge or whether management needs to be notified. A pre-defined P1 or P2 status automates these workflows instantly.
Resource Optimization: P1 and P2 protocols protect engineering and support teams from burnout by ensuring that only genuinely critical events trigger off-hours paging and aggressive escalation paths, reserving routine bug fixes for regular business hours.
Customer Trust and SLA Compliance: For managed service providers (MSPs) and B2B SaaS companies, adhering to P1 and P2 response and resolution targets is a contractual obligation. Meeting these metrics directly protects the bottom line and prevents costly SLA penalty credits.
(This concludes Part 1 of the expert article. The subsequent part will deep-dive into operational workflows, communication protocols, resolution tracking, and post-incident review mechanisms for P1 and P2 events.)
The Operational realities of P1 and P2 management
Moving past the foundational definitions of Priority 1 (P1) and Priority 2 (P2) incidents, the true test of an IT service management (ITSM) or site reliability engineering (SRE) framework lies in its execution under pressure. When an outage occurs, theoretical definitions evaporate, and organizations must rely on rigid protocols, clear role divisions, and disciplined communication structures.
Anatomy of a P1 response lifecycle
A P1 incident does not permit standard working queues or asynchronous troubleshooting. Because the business is actively losing revenue, facing compliance penalties, or experiencing complete operational paralysis, the response must follow a synchronized, time-critical lifecycle:
Immediate Detection and Triage (0–10 Minutes): Automated monitoring tools or user reports flag the anomaly. The service desk or automated ingestion pipeline evaluates the initial blast radius. If core revenue channels or critical safety systems are offline, the ticket is instantly flagged as a P1, overriding all filters.
War Room Activation and Commander Assignment (10–15 Minutes):Unlike lower-priority tickets handled by individual technicians, a P1 requires a dedicated Incident Commander (IC) and a communications lead. The IC coordinates the bridge line or digital war room (e.g., dedicated Slack/Teams channel). Crucially, the IC does not write code or fix systems; their sole job is to manage the timeline, direct investigative sub-teams, and shield engineers from external distractions.
Active Mitigation vs. Root Cause Analysis: The primary mandate of a P1 response is service restoration, not root-cause analysis. If rolling back a recent deployment or routing traffic through a degraded secondary cluster restores functionality, the team executes that workaround immediately. Deep forensic diagnosis is deferred to subsequent problem-management workflows.
Stakeholder and Executive Communication: Transparent, scheduled updates are dispatched to internal leadership and, if public-facing, to status pages. Silence breeds panic; therefore, structured updates every 30 minutes are standard for active P1s until containment is achieved.
Managing the P2 threshold: Urgency meets partial degradation
While P1 scenarios are unambiguous, often characterized by total system unavailability, P2 incidents require careful calibration because they occupy a gray area of partial degradation.
Consider a global retail platform where the main checkout cart functions normally, but the personalized recommendation engine and user profile settings are throwing internal server errors. Customers can still buy products, but conversion rates and user experience are compromised. This is a classic P2 candidate: high business impact due to degraded features, but lacking the total outage footprint of a P1.
Organizations handle P2 escalations by establishing clear boundary rules:
The Workaround Test: If a robust, documented workaround exists that allows internal staff or customers to complete critical tasks without catastrophic friction, the ticket remains a P2. If the workaround is too complex or fails under load, the incident is aggressively escalated to P1 status.
Temporal Triggers: A localized failure can escalate from a P3 to a P2 based strictly on time constraints. For example, a minor database synchronization lag on a reporting tool is normally a P3, but if that lag occurs four hours before quarterly financial reporting closes, urgency shifts dramatically, elevating the ticket to P2.
Avoiding pitfalls: Alert fatigue and Priority Inflation
A common failure mode in enterprise IT environments is priority inflation, colloquially known as the "Cry Wolf" syndrome. When support teams or impatient stakeholders mark every minor bug, cosmetic defect, or delayed request as a P1 or P2 to secure fast-tracked attention, the entire triage system breaks down.
The Cost of Inflation: When everything is treated as urgent, actual emergencies drown in noise. Engineers experience severe alert fatigue, response times for true P1 outages degrade, and executive trust in incident metrics evaporates.
Governance and Auditing: Mature organizations combat priority inflation through strict post-incident reviews (PIRs). If an incident was logged as a P1 but subsequent analysis reveals that only a single non-critical user was affected and no revenue was threatened, the priority classification is formally downgraded during the post-mortem, and the requesting team receives process retraining.
Continuous maturity in Incident management
Mastering P1 and P2 priority definitions transforms an IT organization from a reactive firefighting unit into a resilient, data-driven service provider. By decoupling technical severity from business urgency, codifying strict Service Level Agreements (SLAs), and protecting the integrity of the P1 queue, companies ensure that when critical failures do occur, resources mobilize instantly, downtime is minimized, and customer trust is preserved.