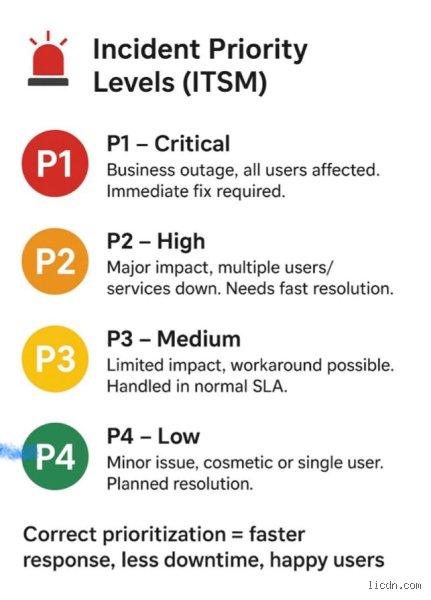
P1, P2, P3, and P4 are incident severity levels used in technology and IT operations to classify the urgency and impact of system issues. These labels help teams decide who responds, how fast, and with what resources.
How severity levels work in tech incidents
These classifications create a clear hierarchy for managing outages. They ensure that critical system failures get immediate attention while minor issues don’t overwhelm on-call staff. Without this structure, teams risk alert fatigue and delayed responses to real emergencies.
P1: full system outage
A P1 incident is the highest severity level. It means a critical system is completely down, affecting all users or core business functions. Examples include a website being unreachable or a payment system failing. Response time is immediate, with teams mobilized right away.
P2: major functionality impaired
P2 incidents involve significant problems that block key features but don’t stop all operations. For instance, users might log in but can’t complete transactions. These require a fast response during business hours, usually within a few hours, but don’t demand an all-hands emergency.
Lower severity levels: P3 and P4
Not every bug crashes the system. Lower tiers handle issues that disrupt convenience or appearance without halting business.
P3: limited impact issues
P3 incidents affect a small group of users or non-critical features. A slow report generator or a failed internal tool sync might be labeled P3. These are typically fixed during regular development cycles and don’t require after-hours intervention.
P4: minor cosmetic problems
P4 is the lowest severity. It includes typos, misaligned buttons, or bugs visible only on outdated browsers. These are logged and addressed when time allows, often grouped into maintenance updates. They don’t affect functionality or revenue.
Common mistakes in incident prioritization
Even with clear labels, teams often misclassify incidents. One common error is labeling too many issues as P1, which dilutes the meaning and leads to response delays when a real crisis hits.
Another mistake is ignoring business impact. A broken internal tool might be technically serious but have low business severity if no one relies on it. Teams should assess who is affected and how, not just what code failed.
People also confuse severity with urgency. Severity measures impact; urgency measures how fast you need to act. A high-severity bug with no immediate user effect may be less urgent than a low-severity issue blocking a time-sensitive launch.
How teams use severity levels effectively
Clear definitions help teams respond quickly and reduce stress during outages. Good incident management includes training, runbooks, and post-mortems to refine classifications over time.
Some organizations use automated tools to escalate issues if they linger too long. A P3 memory leak, for example, might become a P1 if it eventually crashes the system. Monitoring systems can flag these trends before they cause damage.
The goal is not rigid adherence to labels but consistent, thoughtful use. When teams respect the system, they maintain trust, respond faster, and avoid burnout from constant false alarms.