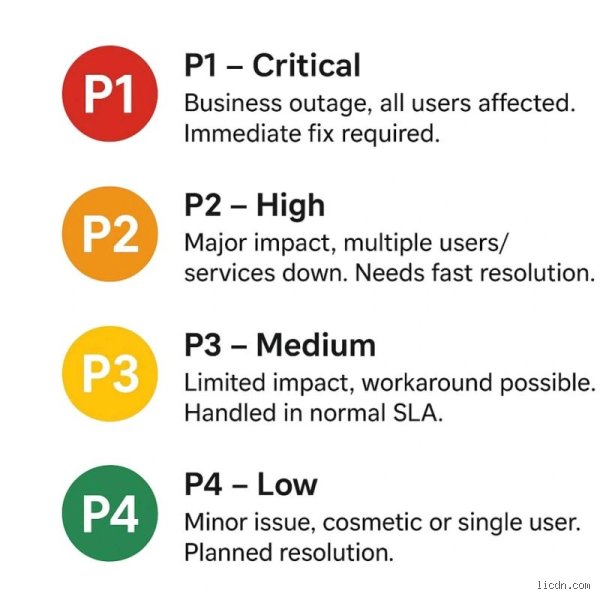
In the high-stakes, fast-paced world of modern software engineering, product management, and IT service delivery, chaos is an occupational hazard. Bugs emerge from the shadows during deployment, security vulnerabilities surface unexpectedly, critical systems experience unforeseen degradation, and feature requests flood in from stakeholders at a relentless pace. Without a structured, universally understood mechanism to triage, categorize, and sequence these competing demands, organizations quickly spiral into operational paralysis. Teams burn out trying to treat every incoming issue as an absolute emergency, leading to "alert fatigue," missed deadlines, compromised code quality, and ultimately, frustrated customers.
Enter the prioritization framework—specifically, the industry-standard P0 through P3 taxonomy.
While seemingly simple—four alphanumeric codes representing descending tiers of urgency—this hierarchical system serves as the foundational bedrock of modern incident management, agile development, and technical support operations. When implemented correctly, it transforms subjective squabbles into objective, data-driven decisions. It aligns cross-functional teams, establishes clear service level agreements (SLAs), protects user trust, and ensures that engineering bandwidth is deployed where it delivers maximum business value.
In this first installment of our comprehensive masterclass, we will deconstruct the philosophy behind priority frameworks, explore the critical distinctions between severity and priority, and dive deep into the first two tiers of the taxonomy: P0 (Critical/Showstopper) and P1 (High). By the end of this section, you will understand not just what these labels mean, but how to define, execute, and govern them with surgical precision within your own organization.
1. The Philosophy of Triage: Priority vs. Severity
Before dissecting individual priority levels, it is vital to clarify a common point of confusion that trips up even seasoned engineering managers: Severity versus Priority. While frequently used interchangeably in casual conversation, conflating these two metrics is a recipe for operational failure.
Severity is a technical measure of the magnitude or impact of a bug or issue on the system itself. It answers the question: How badly is the system broken? For example, if an application crashes completely when a user clicks a specific button, the technical severity is extremely high.
Priority is a business and operational measure of the urgency with which an issue must be addressed. It answers the question: How quickly do we need to fix this, and how important is it relative to everything else on our plate?
To illustrate the distinction, consider a minor typo in the company copyright footer on the main landing page of a billion-dollar e-commerce platform. From a technical perspective, the severity is negligible (it causes no system instability, data loss, or functional impairment). However, if that typo is on the home page during a massive Black Friday marketing campaign, involving the company's legal branding name, the priority might temporarily spike because of reputational risk and brand perception. Conversely, a severe database deadlock affecting a legacy internal reporting tool used by three people on a Friday evening might have high technical severity, but a low immediate business priority if an offline workaround exists until Monday morning.
Understanding this interplay ensures that your engineering teams are solving the right problems at the right time, balancing technical health against customer impact and business revenue.
2. P0: The Emergency / Critical Showstopper
Definition and Core Characteristics
P0 (pronounced "P-Zero") represents the apex of operational urgency. It is the absolute red alert of the software and IT lifecycle. A P0 issue means that the core business functionality is entirely crippled, catastrophic data loss or corruption is actively occurring, or a severe security breach is compromising user data in real time, with no viable workaround available.
When a P0 is declared, standard workflows halt. Normal deployment pipelines are frozen, and designated incident commanders take immediate control. The primary objective of a P0 response is mitigation and restoration of service, rather than immediate root-cause analysis.
Real-World Examples of P0 Incidents
To ground this in practical terms, consider the following scenarios that universally qualify as P0 across industries:
Total System Outage: A SaaS platform's primary production environment goes offline, rendering the application entirely inaccessible to 100% of its user base.
Active Data Breach: Unauthorized actors have gained access to user databases, or sensitive credentials/PII (Personally Identifiable Information) are actively being leaked or exfiltrated.
Payment Processing Failure: An e-commerce checkout gateway experiences a catastrophic failure, completely blocking customers from completing transactions or processing payments across all channels.
Data Corruption Event: A faulty database migration script is actively overwriting or deleting customer records in production without a real-time failover safeguard.
Operational Protocols and Expectations for P0
Handling a P0 requires rigid discipline, pre-established incident response protocols (such as PagerDuty alerts and war rooms), and clear accountability.
Response Time: Immediate (typically within minutes, 24/7/365). Automated monitoring tools should trigger waking alerts for on-call engineers.
Staffing: All-hands-on-deck approach. Senior engineers, tech leads, and relevant product/infrastructure stakeholders are automatically pulled into a dedicated bridge or communication channel (e.g., an incident Slack channel or war room).
Communication Cadence: Stakeholders and executive leadership require regular updates (often every 15 to 30 minutes) until mitigation is achieved. Public status pages must be updated immediately if customers are impacted.
Post-Incident Requirement: Every P0 incident must be followed by a rigorous, blameless post-mortem analysis within 48 to 72 hours to identify root causes, preventative measures, and action items.
3. P1: High Impact / Critical Business Disruption
Definition and Core Characteristics
If P0 is the house actively burning down, P1 (pronounced "P-One") is a major structural fire contained to a critical wing of the building. A P1 issue represents severe degradation of core product functionality or an issue affecting a massive segment of users, but where a complex, painful, or limited workaround exists, or where critical auxiliary systems are impaired without entirely halting core revenue generation.
P1 issues demand immediate attention during business hours and aggressive escalation outside of normal working hours. They threaten user trust, violate high-tier Service Level Agreements (SLAs), and can quickly escalate into P0 emergencies if left unmitigated.
Real-World Examples of P1 Incidents
Partial Outage / Feature Failure: The main application is up, but the core search and recommendation engine is completely non-functional, forcing users to manually browse through unorganized catalogs.
Significant User Subset Impact: A critical bug breaks login functionality specifically for users authenticating via Single Sign-On (SSO) or corporate enterprise accounts, locking out a major B2B enterprise client base while individual consumer logins remain functional.
Performance Degradation: Latency spikes dramatically across the application, causing page load times to exceed 10 seconds and leading to widespread transaction timeouts and frustrated user drop-offs.
Compliance or Regulatory Risk: A non-compliance bug is discovered that violates data privacy regulations (such as GDPR or CCPA requirements), exposing the company to potential legal liability if not patched within a strict regulatory window.
Operational Protocols and Expectations for P1
Response Time: Rapid response required (typically within 1 to 2 hours), regardless of whether it occurs during peak business hours or overnight.
Staffing: Dedicated engineering resources are immediately reassigned from current sprint backlog items to investigate and patch the issue.
Communication Cadence: Status updates provided hourly or bi-hourly to impacted product and customer success teams so they can proactively manage client expectations.
Resolution Target: Hotfixes or patches are deployed rapidly outside of standard release windows following expedited code review and testing protocols.
In the next installment of this masterclass, we will explore the remaining tiers of the framework—P2 (Medium) and P3 (Low)—examine how to manage backlog grooming for lower-priority items, and look at best practices for avoiding priority inflation across growing engineering organizations.
Building upon the foundational definitions of P0 through P3, operationalizing these priority tiers requires more than just assigning labels in a Jira ticket or an incident management tool like PagerDuty. Without robust processes, clear Service Level Agreements (SLAs), and cross-functional buy-in, even the best-defined tier system will descend into chaos.
Let's explore how mature engineering, product, and operations teams operationalize, manage, and evolve their priority frameworks to ensure maximum efficiency, minimal downtime, and team well-being.
1. Bridging Priorities with SLAs, SLOs, and Response Times
Priority levels cannot exist in a vacuum; they must be tightly coupled with measurable expectations for response and resolution. An effective framework maps each priority to strict Service Level Objectives (SLOs) and SLAs.
Operational Rules for Response Times
The 24/7 Rule for P0: P0 incidents typically require an active on-call rotation with automated paging. If a P0 occurs at 3:00 AM on a Sunday, the on-call engineer and incident commander are awakened immediately.
Business Hours vs. Continuous Tracking: For P2 and P3 issues, response timers generally tick only during standard business hours, reflecting that these bugs do not pose an immediate threat to business revenue or customer trust.
2. The Lifecycle of a Priority Ticket: From Triage to Resolution
Managing priorities effectively requires a defined lifecycle. When a ticket enters the backlog or hits an alerting system, it goes through a specific journey.
Step 1: Automated or Manual Triage
When an alert fires or a user submits a bug report, the triage engineer or automated system assigns an initial priority.
Self-Reporting Risk: Users and customer support teams tend to label every issue they experience as "High" or "Critical" because they want swift resolution. Triage protocols must empower engineering teams to recalibrate priorities based on technical impact rather than emotional urgency.
Step 2: Incident Command and War Rooms (For P0/P1)
For critical spikes, a P0 or P1 instantly triggers an incident response protocol:
The Incident Commander (IC): Directs the response, coordinates communication, and keeps stakeholders informed so technical staff can focus entirely on mitigation.
Communication Cadence: Stakeholders receive regular updates via dedicated Slack/Teams channels or status pages. Transparency prevents panic and eliminates duplicate troubleshooting efforts.
Step 3: Mitigation vs. Permanent Resolution
In high-priority situations, speed supersedes perfection.
Mitigation involves rolling back a bad deployment, failing over to a backup database, or enabling a feature flag to turn off a broken service.
Resolution comes later through a proper patch, code refactoring, and comprehensive automated testing.
3. Common Pitfalls in Priority Management
Organizations often struggle with their priority systems due to behavioral and cultural anti-patterns. Recognizing these traps is the first step toward avoiding them.
The "Everything is P0" Anti-Pattern If every bug is marked as P0, then nothing is a P0. This dilutes urgency, leads to severe on-call burnout, and destroys trust between product and engineering teams. If a team experiences constant P0 inflation, leadership must step in to redefine what constitutes true business-halting failure.
Other Dangerous Traps Include:
Priority Creep: Allowing a P3 ticket to slowly morph into a P1 simply because a stakeholder keeps asking about it loudly, bypassing the formal triage process.
Ignoring P3 Backlog Debt: Letting low-priority tickets accumulate indefinitely until the backlog becomes an unsearchable graveyard. Establish a routine grooming cadence to close stale or obsolete P3/P4 tickets.
Lack of Root Cause Analysis (RCA): Failing to conduct blameless post-mortems after P0 or P1 incidents means the organization is doomed to repeat the same failures.
4. Best Practices for Evolving Your Priority Framework
As companies scale from a small startup to a multi-product enterprise, their priority frameworks must adapt. Implement these best practices to keep your system healthy:
Keep Definitions Objective, Not Subjective: Avoid vague guidelines like "feels important." Instead, use concrete metrics: Does this affect more than 50% of active users? Is there a viable workaround? Is revenue directly impacted?
Regularly Audit Priority Accuracy: Once a month, review closed P0 and P1 tickets to verify whether they were accurately classified. If a ticket labeled P0 turned out to be easily workaroundable, adjust your classification criteria.
Automate Priority Assignment Where Possible: Utilize ticketing tool workflows, form validations, and routing rules to guide reporters toward accurate classifications based on impacted components.
Foster Cross-Functional Empathy: Product managers need to understand the cognitive load and stress placed on on-call engineers by high-priority interrupts, while engineers must appreciate the business pressures driving customer requests.
Conclusion
Mastering the use of P0, P1, P2, and P3 priorities is a hallmark of mature, resilient engineering organizations. By establishing clear definitions, tying tiers to realistic SLAs, enforcing strict triage protocols, and avoiding common traps like priority inflation, teams can transform chaos into structured efficiency.
Ultimately, a well-implemented priority framework protects your product's reliability, keeps your customers satisfied, and safeguards your engineering teams from burnout—ensuring everyone knows what matters most, exactly when it matters most.