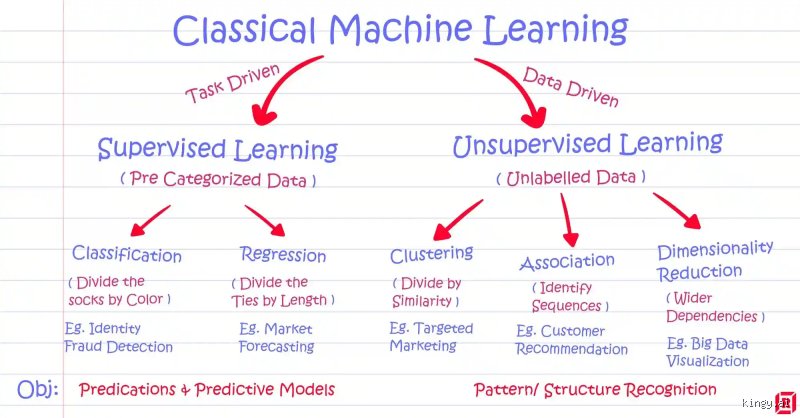
The core question of machine Learning taxonomy
At the intersection of these paradigms lies one of the most widely deployed tools in the data scientist's arsenal: the classification model. From filtering spam emails and diagnosing medical conditions from MRI scans to recognizing handwritten digits and detecting fraudulent financial transactions, classification models touch nearly every facet of modern digital life.
Yet, a recurring question frequently surfaces in data science forums, academic classrooms, and technical interviews: Are classification models strictly supervised, or can they ever be unsupervised?
To answer this question definitively: Classification models are fundamentally and overwhelmingly supervised learning algorithms.
However, stopping at a simple one-sentence answer strips away the rich nuance, architectural variations, and fascinating boundary cases that exist at the edges of modern machine learning. Understanding why classification is classified (pun intended) as a supervised task requires a deep dive into the mechanics of data, the role of ground truth labels, and the philosophical distinction between learning with a teacher versus learning through autonomous exploration.
1. The grand divide: Supervised vs. Unsupervised Learning
To understand why classification models reside firmly within the supervised camp, we must first establish a rigorous baseline of what separates supervised learning from unsupervised learning. These two paradigms represent fundamentally different learning strategies, mirroring how humans acquire knowledge in the physical world.
Supervised Learning: Learning with a teacher
Supervised learning can be conceptualized as learning with an instructor who possesses the answer key. In this paradigm, an algorithm is trained using a dataset consisting of features (input variables, often denoted as XXX) paired with corresponding target labels (the correct output or "ground truth," often denoted as YYY).
The primary objective of a supervised learning algorithm is to learn a mapping function, fff, that can accurately predict the output label YYY given a new, unseen set of input features XXX:
Y=f(X)Y = f(X)Y=f(X)
During the training phase, the model makes predictions, compares those predictions against the actual ground truth labels provided in the training data, and calculates the error (via a loss function). Through optimization techniques like gradient descent, the model iteratively adjusts its internal parameters (weights and biases) to minimize this error.
Unsupervised Learning: Autonomous exploration
Conversely, unsupervised learning operates in the complete absence of a teacher or pre-existing answer keys. The algorithm is fed data containing only input features XXX, with no corresponding target labels YYY.
The goal here is not to predict a specific target or classification, but rather to explore the underlying structure, hidden patterns, probability distributions, or intrinsic groupings within the data itself. Common tasks in unsupervised learning include:
Clustering: Grouping similar data points together based on distance or density metrics (e.g., K-Means, DBSCAN).
Dimensionality Reduction: Compressing high-dimensional data into fewer dimensions while preserving variance (e.g., Principal Component Analysis, t-SNE).
Association Rule Learning: Discovering interesting relations or frequent itemsets in large databases (e.g., market basket analysis).
Given these distinct definitions, where does classification fit? Let us examine the anatomy of a classification problem to see why it requires the scaffolding of supervised learning.
2. The anatomy of a Classification problem
At its core, classification is the task of approximating a mapping function from input variables to discrete output classes or categories. For instance, consider an email filtering system.
[ Incoming Email Features ] ---> [ Classification Model ] ---> [ Output Class: "Spam" or "Not Spam" ]
To build this model, data scientists cannot simply throw thousands of raw emails into an algorithm and expect it to magically discover the concept of "spam." Instead, the process requires a rigorous data preparation pipeline:
Data Collection and Feature Extraction: Raw emails are converted into numerical representations, such as word frequency counts, presence of specific trigger words, sender reputation scores, and formatting markers. These represent our input features (XXX).
Annotation (Ground Truth Labeling): Human reviewers or historical user actions tag each email with an explicit label (YYY): either 1 for spam or 0 for non-spam (ham).
Model Training: The classification algorithm analyzes the relationship between the features and the explicit labels, learning which combinations of word frequencies strongly correlate with the "spam" label.
Evaluation: The model's predictions are directly compared against the known validation labels to calculate accuracy, precision, recall, and F1-score.
Without step two, the explicit provision of ground truth labels, the model would have no target to optimize against. It could group emails based on length or language, but it would have no concept of what "spam" actually means in the context of user intent.
Key Takeaway: Classification is fundamentally a prediction task where the possible outputs (classes) are predefined and explicitly taught to the algorithm through labeled historical data.
3. Why Classification requires Supervision: The role of the Loss function
To appreciate why unsupervised classification is an oxymoron, we must look under the hood at how machine learning models optimize their performance.
Every classification model relies on a loss function (or cost function) to quantify how "wrong" its predictions are. Common examples include Cross-Entropy Loss and Hinge Loss. These mathematical functions require a direct comparison between two entities:
The model's predicted probability distribution over the classes.
The actual, true class label provided in the training dataset.
If a model is trained in an unsupervised environment, the second entity, the true class label, does not exist. Without a reference point for correctness, the loss function cannot be computed. Without a loss function, backpropagation and gradient descent have no directional guidance. The model cannot determine whether adjusting a weight will make it more accurate or more erroneous.
Therefore, the presence of supervision is not merely a stylistic choice in classification; it is a structural necessity for the mathematics of predictive optimization.
4. Common misconceptions: Can unsupervised techniques perform Classification?
While standard classification is strictly supervised, the boundaries of machine learning often blur when practitioners encounter advanced hybrid techniques or misuse terminology. Let's address the common gray areas that lead to the misconception that classification can be unsupervised.
1. Clustering vs. Classification
A frequent point of confusion arises between clustering (unsupervised) and classification (supervised).
Clustering algorithms (like K-Means) group data points based on similarity without knowing what those groups represent. The algorithm might divide a customer dataset into 4 distinct clusters, but it is entirely up to the human data scientist to inspect those clusters and manually interpret what they mean (e.g., "Cluster 1 represents bargain hunters").
Classification algorithms, by contrast, are given predefined classes (before training begins) and are explicitly trained to assign new data points to those specific, named categories.
2. Semi-Supervised Learning and Pseudo-Labeling
In modern machine learning, datasets are frequently massive, but fully labeled data is expensive and time-consuming to acquire. This has given rise to semi-supervised learning, which uses a small amount of labeled data combined with a large pool of unlabeled data.
A popular technique within semi-supervised classification is pseudo-labeling:
A classification model is trained on the small set of labeled data.
The model makes predictions on the unlabeled data.
Predictions that exceed a high confidence threshold are treated as "pseudo-labels" and added to the training set.
The model is retrained on the expanded dataset.
While this incorporates unsupervised data, the core model architecture and final objective remain supervised: the model is still performing classification guided by labels (even if some of those labels were generated by the model itself in an earlier iteration).
Summary of Part 1
Classification models are fundamentally supervised. They require historical input-output pairs (XXX and YYY) to learn a mapping function.
Supervised vs. Unsupervised: Supervised learning relies on explicit ground truth labels and a teacher/instructor paradigm, whereas unsupervised learning explores hidden structures and groupings in unlabeled data.
The Math of Supervision: Classification requires loss functions (like cross-entropy) that depend on knowing the true class labels to guide optimization through gradient descent.
Clustering is not Classification: Unsupervised clustering groups data blindly, leaving interpretation to humans, whereas classification assigns items to predefined, known categories.
In the second part of this expert analysis, we will explore advanced classification architectures, examine edge cases like zero-shot learning and unsupervised domain adaptation, and look at how foundation models are shifting traditional boundaries.
Artificial intelligence dominates nearly every technological landscape. Machine learning models power our daily digital experiences, from email spam filters to medical diagnoses. Classification tasks form the fundamental backbone of these intelligent systems.
Yet, the core nature of how these models learn remains a subject of intense discussion among data scientists. Are they strictly supervised, or can they operate within unsupervised frameworks? Let us explore this conceptual divide in detail.
Traditional classification inherently relies on ground-truth labels. Without knowing what a specific category represents, a standard classifier cannot map input features to discrete output classes.
This strict requirement has defined supervised learning for decades. Early statisticians built algorithms specifically designed to minimize prediction error against known target variables. Logistic regression and support vector machines are classic examples of this paradigm.
However, modern machine learning weaves a complex mix of hybrid methodologies. We no longer live in a simple world of pure, mutually exclusive categorization rules. Data is messy, unstructured, and abundant.
Let us dig into the fascinating mechanics of semi-supervised learning models. This clever approach utilizes a small amount of human-annotated data alongside vast oceans of unlabeled information. It bridges the gap between expensive labeling costs and data scarcity.
Does this architectural choice make the resulting model supervised or unsupervised? There's no consensus on the precise categorization of these hybrid systems. Some purists insist that any foundational reliance on human-provided labels keeps the model firmly in the supervised camp.
Others argue that the heavy lifting performed by unsupervised clustering algorithms during feature learning fundamentally shifts the paradigm. This is where things get complicated for researchers attempting to draw clean, unambiguous conceptual boundaries. Real-world data defies rigid textbook definitions.
It's unclear where the exact line should be drawn in contemporary deep learning architectures. Self-supervised pre-training blurs these historical lines even further. Models learn representations without explicit human guidance before ever seeing a classification target.
people tend to overlook this when they deploy off-the-shelf classifiers into enterprise production environments. They often assume the underlying mathematical mechanics are completely straightforward. They treat classification as a solved, black-and-white problem.
But when a deployed model suddenly encounters an entirely novel cluster of data distribution drift in production, that is a big deal. The learned classification boundaries can become invalid overnight. Model degradation happens silently and rapidly.
So , businesses experience unexpected classification failures in critical automated pipelines, leading to costly errors. Maintaining long-term data integrity requires constant monitoring and retraining. Operational oversight cannot be ignored.
Unsupervised dimensionality reduction techniques like principal component analysis or t-SNE frequently precede classification pipelines. These mathematical transformations help algorithms visualize separable clusters in high-dimensional spaces. Unsupervised preparation directly enhances supervised performance.
Modern transformer models utilize massive self-supervised pre-training objectives before fine-tuning on specific downstream classification tasks. This means the neural network already understands complex linguistic syntax and semantics before seeing a single classification label. The training pipeline is a hybrid masterpiece.
The trouble is that defining a model purely by its final output task ignores its intricate training journey. A classifier might utilize unsupervised feature extractors under the hood. Labeling is often just the final polish on an unsupervised foundation.
not even close when considering fully autonomous, self-correcting classification systems that discover entirely new taxonomies without human intervention. True open-world generalization remains an active and challenging research frontier. Artificial general intelligence is still on the horizon.
While the end task of classification looks decidedly supervised, the broader ecosystem relies heavily on unsupervised foundations. Understanding this dual nature is essential for modern data science practitioners. Context matters immensely in algorithm design.
Categorizing classification models as strictly supervised or unsupervised represents an outdated oversimplification. The future of machine learning belongs to hybrid paradigms that seamlessly leverage the best of both worlds. Innovation thrives at these intersections.
Consider how clustering algorithms group similar data points without any supervision whatsoever. K-means and hierarchical clustering discover hidden structures entirely on their own. They reveal natural groupings in the wild.
When we take those unsupervised clusters and assign human labels to them, we effectively build a classifier. The boundary between discovery and classification becomes porous. This technique proves exceptionally useful in exploratory data analysis.
Anomaly detection models often operate on unsupervised principles to classify outliers. They flag fraudulent transactions without historical examples of fraud. This turns traditional classification thinking upside down.
Let us examine how neural networks handle representation learning. Autoencoders compress data into lower-dimensional bottlenecks without labels. The encoder portion extracts vital features independently.
Once these features are learned, a simple linear classifier can be slapped on top. This requires only a fraction of the labeled data normally needed. Efficiency skyrockets through this clever combination.
Therefore, treating supervision as a binary switch is mathematically incorrect. Machine learning exists on a broad, continuous spectrum. Every model occupies a unique spot on this methodological gradient.
Practitioners must evaluate their specific use case requirements carefully. Label scarcity often dictates whether a purely supervised approach is even feasible. Resource constraints shape architectural decisions daily.
As data volumes continue to explode globally, unsupervised and self-supervised methods will only grow in importance. We cannot manually label every petabyte of information generated. Automated discovery is the only scalable path forward.
Classification is less about the method of training and more about the objective function. Whether the target is provided by humans or discovered by math, the output categorizes reality. Both paths lead to structured understanding.
Question 2
While unsupervised and self-supervised methods are advancing at a breathtaking pace, they are unlikely to completely replace supervised classification in the near future. High-stakes domains like medical diagnostics and legal compliance demand absolute precision and explicit human validation that only supervised frameworks can reliably provide. Unsupervised models excel at discovery and representation, but they still struggle to interpret complex human intent without guided feedback loops. Therefore, the future of artificial intelligence lies in synergistic collaboration rather than total replacement of one paradigm by another. Both approaches will continue to evolve side by side to solve increasingly sophisticated real-world challenges.