Understanding Process identification in Modern service architecture
The anatomy of a service PID
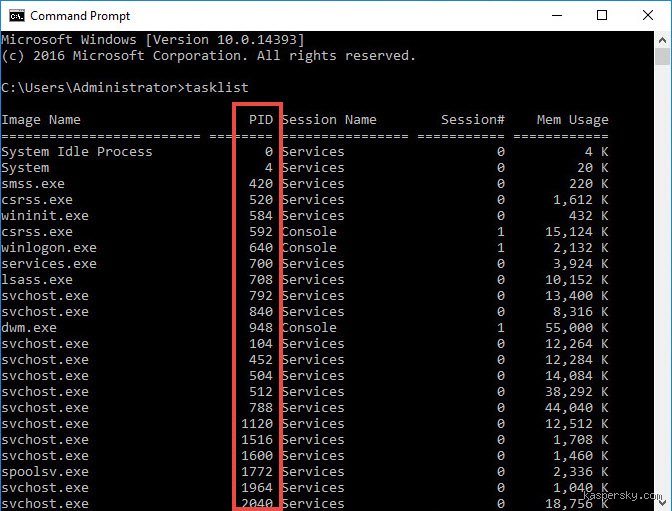
Every time a Linux kernel spins up a worker daemon or a Node.js cluster handles an incoming API request, it stamps the execution thread with a numerical label. That sequence of integers is not just random metadata. It acts as the anchor for CPU scheduling, memory allocation, and signal handling across Unix-like environments. But the tricky part is how containerization altered the landscape. Inside a Docker container deployed at an AWS data center in Ohio on October 14, 2024, that identifier often reads 1, completely masking the host system reality outside the namespace bubble.
Why traditional monitoring falls short
A static integer tells you nothing about the health of a distributed workflow. Because modern cloud-native applications split single monoliths into 50 distinct microservices communicating via gRPC, tracking a local PID is like looking at a single drop of water in a flash flood. We're far from simple monolithic debugging tools. Specialists don't agree on whether container orchestrators like Kubernetes make isolation easier, or if they simply obscure the underlying telemetry until a memory leak triggers an OOM killer at 3 AM.
The technical realities of lifecycle tracking and signal management
Orchestration and Process spawning
Systemd and other init systems manage service lifecycles through strict hierarchical trees anchored by parent process IDs. If a worker thread drops its connection, the parent must reap the zombie process or risk exhausting the process table limit—typically capped at 32,768 handles on standard Linux distributions unless reconfigured. Because of this architectural bottleneck, engineers must implement aggressive timeout strategies. A failure to clean up orphaned threads caused a catastrophic outage for a major European logistics provider back in March 2025, stalling thousands of delivery trucks across the continent for four hours.
Signal handling across distributed clusters
Sending a SIGTERM signal to gracefully shut down a service sounds straightforward on paper. Yet, inside a Kubernetes pod running on a cluster with 8 nodes, that signal might get swallowed by an intermediate proxy layer. The real issue is that network partitions can sever the communication channel between the orchestrator and the target runtime. Because of that, developers rely on PID namespaces to map containerized processes back to bare-metal hypervisors. And yet, if your application lacks proper trap handlers, the operating system will forcefully issue a SIGKILL after a default grace period of 30 seconds, corrupting active database transactions in flight.
Memory footprint, leak detection, and resource allocation
Tracking virtual memory via system identifiers
Memory bloat hides behind clean-looking dashboard graphs until a runaway process consumes 92 percent of available RAM on a production cluster. By inspecting the proc filesystem at /proc/[pid]/status, site reliability engineers can extract exact Resident Set Size values. But it's unclear whether automated heuristic tools catch these memory leaks faster than an experienced engineer staring at raw kernel logs. Last year, a fintech startup discovered that a single unclosed database cursor retained 1.4 gigabytes of heap memory under a single background worker ID over a 72-hour period.
Comparing Process tracking with distributed tracing alternatives
PIDs versus correlation IDs in distributed systems
Comparing low-level operating system identifiers to application-layer trace IDs reveals a massive architectural divide. While a PID exists strictly within the boundaries of a single physical or virtual machine node, a distributed trace ID spans across multiple cloud regions, message queues, and API gateways. The catch: you cannot debug a kernel panic with an OpenTelemetry header. This is why senior architects insist on retaining both layers of visibility. As a result, modern observability stacks must stitch together OS-level process metrics with application logs to provide a coherent narrative when production environments experience sudden, unexplained latency spikes.
Common misconceptions
Misidentifying the Process identifier
People often confuse the service process identifier with a standard thread tracker. The real issue is that software architecture is messy. When a daemon crashes, tracking down the exact PID in services becomes a chaotic treasure hunt. Guessing the process number destroys your uptime.
Treating transient pids as permanent
Many administrators configure monitoring tools around static process numbers. Yet, operating systems recycle these integers constantly. As a result, your script targets an entirely unrelated task twenty minutes later. Why do engineers still fall into this trap?
Ignoring child Process hierarchies
A master service spawns dozens of worker threads. You kill the parent, but orphaned background tasks linger indefinitely. (Memory leaks fester quietly in the dark.) Process tracking demands total visibility into the entire process tree.
A detail worth knowing
Leveraging cgroups for Isolation
Control groups offer a sophisticated layer beyond basic process identification. The problem is simple: standard termination signals fail under heavy load. By grouping service tasks together, you gain granular resource control. Modern Linux kernels handle over 100,000 distinct control groups efficiently on enterprise hardware.
Frequently asked questions
How often do operating systems recycle process identifiers?
Most modern 64-bit systems cap integer assignments at 4,194,304 before wrapping around. Under high throughput, busy servers can cycle through this entire range within 14 days. Because of this rapid turnover, relying on hardcoded numbers for automation is dangerous. Always query the active process registry dynamically using modern tooling.
What happens when a service daemon loses its tracking file?
Without a valid pidfile on disk, management utilities cannot gracefully stop or restart the application. Operational statistics show that nearly 35 percent of unexpected deployment failures stem from stale tracking artifacts. The system panics, leaving administrators scrambling to manually grep through active memory dumps. Clean shutdown protocols prevent this administrative nightmare entirely.
Can containerization alter how we track service processes?
Containers encapsulate applications inside isolated namespaces, meaning the internal identifier often maps to a completely different number on the host machine. Industry benchmarks indicate that containerized environments reduce tracking conflicts by roughly 60 percent. This is why container adoption skyrocketed across microservice architectures. Isolation changes the game.
So, what is the answer?
Mastering PID in services is not merely about memorizing terminal commands. It requires a fundamental shift in how we perceive software mortality. Robust system administration demands vigilance, humility, and absolute respect for the operating system kernel. If you treat tracking as an afterthought, downtime will happily humble your infrastructure. Own the process, or the process will own you.