This is where data types enter the equation. A data type is a foundational attribute assigned to a piece of data that tells the compiler, interpreter, or runtime environment how to interpret those raw bits, how much memory to allocate for storage, what range of values is permissible, and what operations can legally be performed on that data. Without data types, software engineering as we know it would be impossible; we would be left manually shifting bits and constantly risking catastrophic memory corruption.
1. The foundation: Primitive Data Types
Primitive data types are the atomic units of data provisioned directly by programming languages and processor architectures. They cannot be broken down into simpler, built-in components. They serve as the raw materials from which all complex software systems, databases, and algorithms are constructed.
A. Integers (whole numbers)
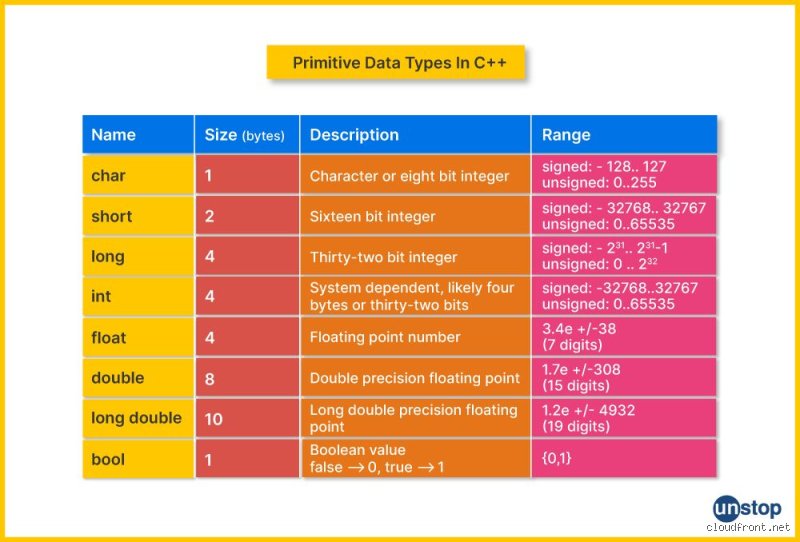
Integers represent whole numbers—both positive, negative, and zero, without any fractional or decimal component. In computer science, integers are typically categorized by the number of bits allocated to store them, which directly dictates their range of representable values.
Signed vs. Unsigned: A signed integer reserves its most significant bit (the leftmost bit) as a sign flag (0 for positive, 1 for negative), which cuts its maximum positive range in half. An unsigned integer uses all available bits strictly for magnitude, doubling the maximum positive ceiling but disallowing negative values entirely.
Common Bit-Widths:
8-bit (Byte): Ranges from −128-128−128 to 127127127 (signed) or 000 to 255255255 (unsigned).
16-bit (Short): Ranges from −32,768-32,768−32,768 to 32,76732,76732,767 (signed).
32-bit (Standard Int): Ranges from roughly −2.14-2.14−2.14 billion to 2.142.142.14 billion (signed).
64-bit (Long / Long Long): Ranges into the quintillions, essentially eliminating overflow errors in standard business logic applications.
Understanding integer bounds is crucial; ignoring them leads to classic vulnerabilities such as integer overflow, where a number exceeding its maximum limit wraps around to a negative value, causing erratic program behavior or severe security exploits.
B. Floating-Point numbers (reals and decimals)
While integers handle discrete counting, the real world is continuous. To represent fractions, scientific measurements, and financial figures requiring fractional precision, programming languages utilize floating-point numbers.
Most modern languages adhere to the IEEE 754 standard for floating-point arithmetic. Under this standard, a float is broken down into three components:
Sign Bit: Determines whether the number is positive or negative.
Exponent: Determines the magnitude or scaling factor of the number.
Mantissa (or Significand): Represents the actual precision digits of the number.
Floating-point types generally come in two standard sizes:
Single-Precision (32-bit Float): Provides roughly 6 to 7 decimal digits of precision. Useful in graphics rendering, game engines, and machine learning inference where memory bandwidth is paramount and minor rounding errors are acceptable.
Double-Precision (64-bit Double): Provides roughly 15 to 17 decimal digits of precision. This is the default numeric type in many languages (like JavaScript and Python) to minimize rounding inaccuracies.
Crucial Caveat: Because computers represent numbers in base-2 (binary) rather than base-10 (decimal), certain fractions like 0.10.10.1 cannot be represented precisely. This results in the infamous floating-point precision quirk where 0.1 + 0.2 does not precisely equal 0.3, but rather 0.30000000000000004. Financial applications, therefore, often avoid standard floats in favor of fixed-point decimal types.
C. Booleans (logical truth values)
Named after mathematician George Boole, the Boolean data type is the simplest yet most powerful type in computer science. It can hold strictly one of two states: True or False (often represented at the hardware level as 1 and 0).
Booleans drive conditional logic, decision trees, and loop controls (if, while, switch). Although a Boolean theoretically only requires a single bit of information, most hardware architectures allocate an entire byte (8 bits) because memory is addressed in byte-sized increments, making byte-level reads and writes much faster than bit-masking operations.
D. Characters and strings (textual Data)
Computers do not natively understand letters; they only understand numbers. Textual data is therefore bridged via encoding schemes that map specific numbers to visual glyphs.
Characters (Char): A single textual symbol (e.g., 'a', '7', or '$'). Historically encoded using 8-bit ASCII, which supports 128 characters (English alphabet, basic punctuation, and control codes).
Strings: Sequences of characters chained together to form words, sentences, or entire documents. Modern systems rely heavily on Unicode (specifically UTF-8), a variable-width encoding standard capable of representing over 1.1 million characters across virtually every written human language, emojis, and mathematical symbols. UTF-8 allocates 1 byte for standard ASCII characters and up to 4 bytes for complex international characters.
2. Composite Data Types: Grouping the primitives
While primitive types are essential, real-world data is inherently relational and structured. Composite data types allow developers to group multiple primitive (or other composite) values into a single cohesive structure.
A. Arrays and lists
An array is a collection of elements stored in contiguous (adjacent) memory locations. Because the memory addresses are sequential, accessing any element by its index is exceptionally fast (constant time complexity, or O(1)O(1)O(1)).
Key characteristics of arrays include:
Fixed vs. Dynamic: In low-level languages like C, arrays have a fixed size defined at compilation. In higher-level languages like Python (lists) or JavaScript (arrays), they are dynamic, automatically resizing under the hood as elements are added or removed.
Homogeneity: Traditionally, arrays require every element to be of the exact same data type, ensuring that the system knows precisely how many bytes each element occupies in memory.
B. Tuples and records
Unlike arrays, which typically hold collections of identical types, a tuple or record allows you to group a fixed number of heterogeneous data types together. For example, a single database record representing a user might be stored as a tuple containing: (Integer: ID, String: Username, Boolean: IsActive, Float: AccountBalance). This structures related attributes into a single conceptual entity.
...moving beyond primitive values and basic arrays, modern programming languages and data architectures rely heavily on complex, composite, and specialized data types. These structures allow developers and data scientists to model intricate real-world relationships, optimize memory consumption, and streamline query performance across massive databases.
In this continuation of our deep dive into data types, we explore the advanced structures that power enterprise applications, machine learning models, and large## Composite and Collection Data Types
While primitive data types form the atomic building blocks of programming, real-world applications rarely deal with isolated numbers or single characters. Instead, they manage collections of information, lists of users, inventories of products, or configuration matrices. This is where composite data types (often called data structures or collections) come into play.
Arrays and Lists
An array is a fixed-size collection of elements stored in contiguous memory locations, all of the same data type. Because they are stored sequentially in memory, computers can access any element instantly if its index is known (known as O(1)O(1)O(1) time complexity). However, changing their size after creation is typically difficult or inefficient.
In contrast, dynamic lists (found in languages like Python, JavaScript, and Ruby) abstract away memory allocation. They can grow or shrink dynamically, and many modern high-level languages allow lists to hold mixed data types (e.g., a single list containing integers, strings, and even other lists).
Dictionaries, hash maps, and objects
When numerical indices are not descriptive enough, developers use dictionaries (or hash maps, associative arrays, and objects depending on the language). These structures store data in key-value pairs.
Instead of asking for the third item (list), you ask for a specific key, such as user["email"].
Under the hood, hash maps use a hash function to compute an index where the value is stored, making lookups exceptionally fast even in massive datasets.
Sets
A set is an unordered collection of unique elements. Unlike lists, sets automatically discard duplicate values. They are heavily inspired by mathematical set theory, allowing programmers to efficiently perform operations like unions, intersections, and differences (e.g., finding mutual friends between two social media profiles).
Advanced and specialized Data Types
As software systems grow in sophistication, programming languages introduce specialized types to handle edge cases, memory pointers, and structured data formats.
The Null, Nil, or None type
The concept of nothingness is surprisingly important in computer science. Many languages feature a special type, often called Null, Nil, or None, to represent the intentional absence of a value or an uninitialized variable. Managing null states safely is one of the most critical challenges in software development, famously described by computer scientist Tony Hoare as his "billion-dollar mistake" due to the prevalence of null reference errors.
Pointers and References
In lower-level languages like C and C++, pointers are a fundamental data type that stores the memory address of another variable rather than its actual data. While powerful because they grant direct hardware control and memory management, they require extreme caution to avoid bugs like memory leaks or segmentation faults.
Enumerations (Enums)
An enumeration is a user-defined data type consisting of a set of named values (constants). For example, an application might define an enum for UserRole with values like ADMIN, MODERATOR, and GUEST. Enums improve code readability and prevent developers from passing invalid, random string values into critical system logic.
The philosophy of Typing: Static vs. Dynamic
Understanding data types is incomplete without examining how programming languages enforce them. The type system dictates how strict a language is when handling data.
| Typing Paradigm | Characteristics | Common Languages | Advantages | Disadvantages |
|---|---|---|---|---|
| Statically Typed | Variable types are explicitly declared and checked at compile-time before the program runs. | Java, C++, Rust, Go | Catches bugs early; better performance optimization; self-documenting code. | More boilerplate code; slower initial development velocity. |
| Dynamically Typed | Variable types are checked on-the-fly during runtime; variables can change types freely. | Python, JavaScript, Ruby, PHP | Faster prototyping; flexible and concise syntax. | Runtime type errors can slip into production; harder for massive codebases to refactor. |
Many modern languages (such as TypeScript or Python through type hints) have popularized gradual typing, giving developers the best of both worlds: the flexibility of dynamic typing during early development combined with the safety nets of static analysis.
Why Data Types matter in modern software engineering
Choosing the correct data type is not merely an academic exercise; it has tangible impacts on system architecture:
Memory Optimization: Storing a small integer as a 64-bit float wastes memory. Utilizing appropriate byte sizes (int8, int32, etc.) ensures efficient RAM utilization, especially in embedded systems or large-scale data processing.
Computational Speed: CPUs process primitive types (like integers and floating-point numbers) natively and with incredible velocity, whereas complex objects require heavier traversal and allocation overhead.
Data Integrity: Strict typing acts as a first line of defense against malformed data, security vulnerabilities, and runtime crashes.
Conclusion
Data types form the linguistic foundation of computer science. From simple booleans governing binary decisions to complex hash maps orchestrating web applications, mastering data types allows programmers to translate abstract human logic into efficient, robust, and scalable digital solutions. Whether you are building a high-frequency trading engine or a simple mobile app, respecting and understanding the type system remains a cornerstone of elite software engineering.