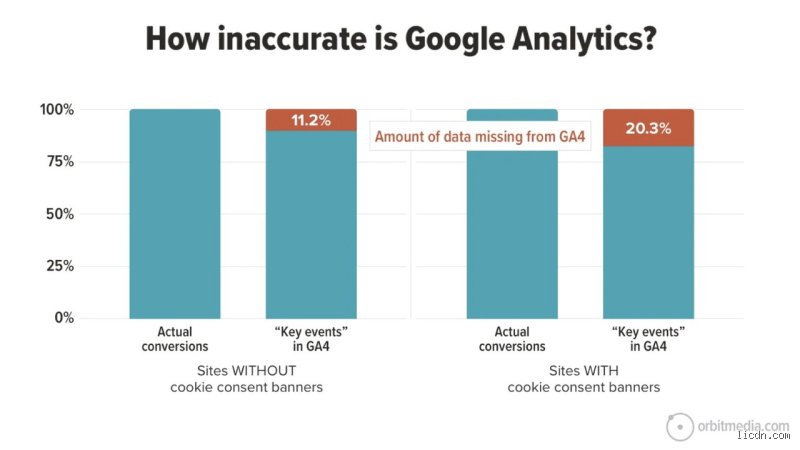
Yet, beneath the polished graphs of Google Analytics 4 (GA4) lies a complex ecosystem of estimation, data loss, browser-level privacy constraints, and probabilistic modeling. To answer the question "Is Google Analytics data accurate?" requires moving past a binary yes-or-no. The truth is more nuanced: Google Analytics is an exceptional tool for tracking directional trends, ranking marketing channels, and spotting sudden anomalies, but it is frequently a flawed instrument for absolute accounting or financial reconciliation.
Understanding why requires dissecting how data is collected, filtered, sampled, and modeled in the modern web environment.
1. The mechanics of discrepancy: Why GA4 differs from your backend
One of the most jarring realizations for website owners launching a new tracking setup is that Google Analytics numbers rarely match their backend databases, customer relationship management (CRM) systems, or payment processors like Stripe and Shopify.
When a customer completes a purchase, a payment gateway logs an exact financial transaction because money literally changed hands. That is ground-truth data. Google Analytics, by contrast, relies on a client-side JavaScript snippet (gtag.js or Google Tag Manager) executing inside the user's browser. This fundamental architectural difference introduces several points of failure:
Client-Side Execution Failures: If a user closes a browser tab the microsecond a payment succeeds, before the tracking script completely fires and transmits the network payload back to Google's servers, the conversion is lost to GA4 while remaining safely captured in the backend database.
Ad Blockers and Privacy Extensions: Millions of internet users deploy browser extensions (such as uBlock Origin, AdBlock Plus, or Brave's built-in shield) that explicitly block requests destined for known analytics domains like google-analytics.com.
Network Restrictions and Firewalls: Corporate IT policies, school networks, and strict virtual private networks (VPNs) often block tracking scripts entirely to preserve bandwidth and privacy, completely blinding analytics platforms to visits from those networks.
Consequently, standard GA4 implementations routinely underreport traffic and conversions by anywhere from 10% to 30% compared to actual backend server records, even on healthy websites.
2. The Privacy revolution: Consent banners and modelled Data
The regulatory landscape—spearheaded by Europe’s General Data Protection Regulation (GDPR), the California Consumer Privacy Act (CCPA), and similar global privacy laws—has fundamentally altered data collection. Today, visitors across the globe are greeted by cookie consent banners upon arriving at a website.
When a user declines tracking or refuses marketing cookies:
Traditional collection mechanisms are legally and technically prohibited from dropping identifying cookies or tracking user journeys across sessions.
In response, Google introduced Consent Mode and behavioral modeling within GA4.
Behavioral modeling uses machine learning to estimate the behavior of users who decline consent based on the behavior of similar users who accepted it. While this fills statistical gaps and prevents dashboards from looking entirely hollow, it means that a significant portion of the metrics you view are no longer raw, observed data points, they are machine-learning estimations. Google applies these models only when it detects "high confidence," but the platform rarely publishes a clear margin of error or confidence interval for those estimations.
3. Data Sampling, Thresholding, and the (other) Row
Even after data successfully reaches Google’s servers, how it is stored and displayed introduces further deviations. Heavy data manipulation occurs through three distinct mechanisms inside GA4:
Data Sampling: When an ad-hoc report or Exploration query analyzes a volume exceeding standard thresholds (10 million events for standard properties), GA4 analyzes a representative subset of data and extrapolates the rest. While helpful for speed, sampled reports lose granular precision.
Data Thresholding: Designed to protect user anonymity, Google automatically withholds rows in reports containing demographic or search query data if the user count drops below a system-defined minimum. These rows vanish entirely, leading analysts to mistakenly assume traffic was lost when it was merely obscured.
The (other) Row: When high-cardinality dimensions (such as long URLs with unique tracking parameters or custom user IDs) exceed table limits, GA4 lumps less common values into a single catch-all row, distorting specific traffic breakdowns.
Summary of the first part
Google Analytics is a sophisticated statistical telescope rather than an accountant's balance sheet. Accepting its structural limitations, such as browser blocking, consent modeling, and data thresholding, allows modern organizations to harness its true superpower: identifying reliable marketing trends and user engagement patterns over time.
The impact of regulatory shifts and Privacy frameworks
As privacy regulations like the European Union's General Data Protection Regulation (GDPR), the California Consumer Privacy Act (CCPA), and subsequent global privacy frameworks have matured, the methodology behind web data collection has fundamentally shifted. Google Analytics 4 (GA4) was engineered with these privacy realities in mind, introducing features like IP anonymization by default and flexible data retention controls. However, these very privacy-centric adaptations introduce inherent friction regarding absolute data accuracy.
The most prominent driver of data discrepancy is the widespread adoption of cookie consent banners. In jurisdictions requiring strict opt-in compliance, a significant percentage of visitors either explicitly reject tracking banners, dismiss them, or leave the site before interacting.
When a user declines consent, standard client-side implementation prevents the Google Tag from firing or setting persistent identifiers (such as the primary _ga cookie).
Consequently, entire segments of organic, paid, and direct traffic remain entirely unrecorded in standard reports.
While Google has introduced Consent Mode (both Basic and Advanced variants) to bridge these gaps via cookieless measurement pings and behavioral modeling, modeled data is an estimation rather than a direct observation. For organizations relying on exact counts, this introduces a philosophical and technical dilemma: balancing legal compliance with empirical precision.
Technical discrepancies: Client-Side limitations and bot Filtering
Beyond regulatory consent walls, technical mechanisms on the modern web actively obstruct data collection. Understanding why Google Analytics totals rarely match server logs or database records requires examining three core technical bottlenecks:
Ad Blockers and Privacy Browsers: A substantial share of global internet users, particularly on desktop devices and among tech-savvy or developer demographics, utilize browser extensions or built-in privacy browsers that explicitly block Google’s measurement scripts (gtag.js or analytics.js). If a tracking script fails to load because its domain or signature is blacklisted, the user becomes entirely invisible to GA4, regardless of their consent preferences.
The JavaScript Execution Barrier: GA4 relies strictly on client-side JavaScript execution. If a user's browser drops connection prematurely, restricts script execution, or encounters rendering errors before the tracking payload transmits, the session is lost. Server-side tagging implementations mitigate some of these drop-offs by proxying measurement through a first-party cloud server, but they do not bypass regulatory opt-outs.
Automated Traffic and Algorithmic Filtering: While GA4 automatically filters known bot traffic, the continuous evolution of sophisticated scrapers, AI web crawlers, and data-center automation means that some non-human traffic inevitably slips past standard filters. Conversely, aggressive corporate firewalls or Virtual Private Networks (VPNs) can mask human users or scramble geographic data, distorting user acquisition metrics.
Reconciling GA4 Data with other sources
A frequent source of frustration for analysts is the inevitable mismatch between Google Analytics metrics and data from parallel platforms, most notably Google Search Console (GSC) or e-commerce backend databases.
Clicks vs. Sessions: GSC measures external discovery by counting raw clicks on Search Engine Result Pages (SERPs). GA4 measures internal engagement by counting sessions, which begin only after the tracking script successfully executes on the destination page. A user may click a search result (registering in GSC), but if they close the tab before the page finishes loading or if an ad blocker blocks the script, GA4 records nothing.
Attribution Variance: Discrepancies also arise from differing attribution models. While platforms like GSC or external ad networks often credit the last non-direct click or view, GA4 default reports utilize Data-Driven Attribution (DDA), distributing credit fractionally across multiple touchpoints in a user's conversion path.
Practical strategies for navigating inaccuracy
Absolute 100% data perfection in web analytics is a statistical impossibility. However, analytical integrity can be maintained by adopting a pragmatic framework:
Treat Metrics as Trends, Not Absolute Truths: Focus on directional movement rather than exact integer counts. A 20% traffic increase month-over-month is valuable insight, even if the underlying absolute visitor count is underreported by a predictable margin due to ad blocking.
Triangulate Data Streams: Never rely on a single dashboard. Cross-reference GA4 engagement trends with CRM records, server-side access logs, payment gateway receipts, and platform-specific advertising reports.
Audit Tag Implementation Regularly: Ensure that tracking codes are uniformly applied across all subdomains and templates, and verify that Consent Mode configurations correctly handle consent updates without double-counting or suppressing valid data.
By acknowledging these systemic limitations and implementing robust cross-verification protocols, data-driven teams can extract reliable, actionable intelligence from Google Analytics while remaining fully compliant with modern privacy standards.