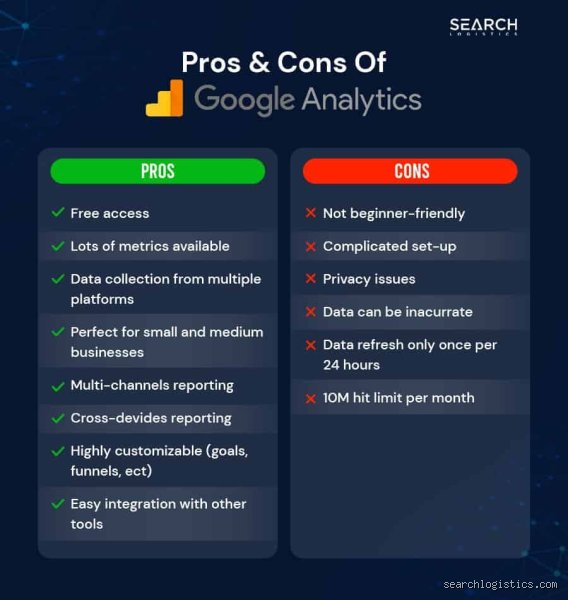
For nearly two decades, Google Analytics has occupied an almost unchallenged throne as the undisputed standard for web traffic measurement and digital analytics. From solo bloggers to Fortune 500 enterprises, millions of websites have integrated its tracking snippet into their source code without a second thought. For the vast majority of digital marketers, product managers, and business owners, Google Analytics (and its modern evolution, Google Analytics 4, or GA4) represents the default starting point for understanding user behavior. It is free (in its standard tier), ubiquitous, seamlessly integrated with the broader Google marketing ecosystem, and supported by an endless ocean of tutorials, certifications, and community forums.
However, as the digital landscape undergoes seismic shifts—driven by escalating privacy regulations, a cultural rebellion against surveillance capitalism, evolving browser technologies, and the relentless complexity of modern user journeys—relying blindly on Google Analytics comes with profound, often overlooked liabilities. While the platform excels at capturing high-level macro trends and aggregate traffic volumes, an uncritical reliance on it can introduce systemic blind spots, data distortion, operational friction, and severe compliance risks.
In this first part of our comprehensive expert analysis, we unpack the foundational downsides of Google Analytics. We will explore how its fundamental sampling limitations distort strategic insights, how its transition to event-based data models creates steep steep learning curves and reporting fragmentation, and how the platform's architectural design inherently struggles with modern, multi-device, cross-platform consumer behaviors.
1. The Illusion of Complete Accuracy: Data Sampling and Thresholding
One of the most insidious misconceptions surrounding Google Analytics is that the numbers staring back at you from your dashboard represent absolute, unvarnished truth. In reality, unless you operate a website with very low traffic volumes or subscribe to the premium (and prohibitively expensive) Google Analytics 360 tier, much of the data you see is subject to algorithmic estimation, sampling, and data thresholding.
Understanding the Mechanics of Sampling
Google Analytics processes massive volumes of incoming user interactions in real time. To manage computational load and maintain acceptable reporting speed for standard properties, Google frequently employs data sampling. Instead of analyzing 100% of the raw event hits hitting your tracking endpoints, the system may analyze a statistically representative subset (for instance, 10% or 20% of your total traffic) and extrapolate those findings across your entire audience.
While statisticians will argue that a properly sampled dataset can accurately reflect broader trends, in digital marketing and conversion rate optimization, precision matters. When you are analyzing high-intent micro-conversions, niche user segments, high-value B2B traffic flows, or low-volume e-commerce transaction funnels, sampling introduces dangerous variances:
Volatility in Reporting: If you run a report on a specific campaign segment over a narrow date range, refreshing the report a few minutes later can yield noticeably different numbers because a different sample slice was processed.
The "Other" Row Phenomenon: When high-cardinality dimensions (such as highly specific event parameters, custom user IDs, or extensive UTM parameter combinations) exceed processing limits, Google aggregates the excess data into an obscure row labeled
(other). This effectively vaporizes granularity, blinding analysts to long-tail user behaviors and specific niche interactions that could hold the key to optimization breakthroughs.
Privacy Thresholding and Signal Loss
Compounding the sampling issue in GA4 is data thresholding. Designed to protect individual user privacy, Google applies strict thresholding rules to properties that cross certain low-traffic or identifiable-user thresholds (especially when Google Signals is enabled, or when demographic and interest reports are active).
When thresholding kicks in, Google deliberately withholds data from your standard reports to prevent the identification of individual users. For organizations operating medium-traffic websites, this manifests as mysteriously empty rows, suppressed data ranges, and a pervasive sense of opacity. You are left paying for a tool that actively hides your own data in the name of privacy compliance—yet leaves you vulnerable to the regulatory risks associated with relying on Google’s proprietary data handling practices in the first place.
2. The Paradigm Shift and Steep Learning Curve of GA4
The forced migration from Universal Analytics (UA) to Google Analytics 4 (GA4) was billed by Google as a modernization effort built for a privacy-first, cross-platform future. In practice, for millions of marketing professionals, analysts, and business stakeholders, it felt less like an upgrade and more like a disruptive demolition of established workflows.
The Death of the Session and the Rise of the Event-Centric Model
In Universal Analytics, the conceptual universe revolved around sessions and pageviews. A user arrived, a session started, they viewed some pages, triggered some predefined interactions, and the session ended. It mapped neatly onto traditional website structures.
GA4 discarded this paradigm entirely, replacing it with an event-based data model. In GA4, virtually everything—from a page view and a file download to a video play and a scroll—is an "event" accompanied by a flexible schema of parameters.
Conceptual Friction: While objectively more flexible for tracking complex mobile apps and hybrid web-app environments, this shift requires a profound cognitive rewiring for traditional marketers.
Loss of Historical Continuity: Organizations lost historical year-over-year comparability overnight. Trend lines that took years to establish in Universal Analytics could not be directly or cleanly mapped onto GA4 equivalents, effectively resetting organizational memory regarding digital baseline metrics.
Configuration Complexity and Implementation Fatigue
Setting up GA4 correctly is no longer a matter of simply pasting a basic JavaScript snippet into your header tag. Achieving robust, reliable tracking requires deep technical fluency with Google Tag Manager (GTM), custom event parameter architecture, data streams, user-property mapping, and cross-domain configuration.
Because out-of-the-box tracking in GA4 is notoriously bare-bones—capturing only rudimentary interactions like page_view, scroll, and file_download—every organization must custom-engineer its own tracking taxonomy. This introduces enormous room for human error:
Misconfigured Triggers: A single typo in a custom event parameter name can break an entire conversion funnel.
Maintenance Burden: As websites undergo redesigns, content updates, or platform migrations, custom GA4 implementations frequently break silently, leading to weeks or months of corrupted or missing data before anyone notices.
Resource Drain: Small to mid-sized businesses are forced to hire specialized analytics engineers or external consultants simply to keep their basic reporting infrastructure operational, turning what should be a plug-and-play tool into an ongoing budgetary and operational drain.
3. The Multi-Device Blind Spot and Identity Resolution Failures
Modern consumer journeys are notoriously non-linear and fragmented. A typical user might discover a product via an ad on their smartphone while commuting, research detailed specifications on a desktop computer at work later that day, and finally complete the purchase on a tablet while sitting on the couch.
How well does Google Analytics bridge these dots? The short answer is: inadequately.
The Limitations of Cookie-Based and Device-Specific Tracking
Historically, web analytics relied heavily on third-party cookies (now largely deprecated or blocked by privacy-conscious browsers like Safari and Firefox) and first-party cookies tied to individual browsers and devices.
The Siloed User Problem: If a single human being interacts with your website across three different devices and two different browsers, Google Analytics will typically record them as three entirely distinct users.
Distorted Attribution: This fragmentation severely skews attribution modeling. Top-of-funnel mobile discovery channels are systematically undervalued because the conversion is often credited exclusively to the last-touch desktop session where the transaction physically occurred.
The Double-Edged Sword of Google Signals
To combat device fragmentation, Google introduced Google Signals, which attempts to stitch user journeys together using data from users who are signed into their Google Accounts and have ad personalization turned on.
While this sounds like a clever solution, it introduces major structural drawbacks:
Sample Bias: Google Signals only captures data from a subset of your overall audience—specifically, those who are logged into Google and opted-in. Extrapolating this biased sample across your entire user base skews behavioral metrics.
Data Discrepancies: Activating Google Signals in GA4 often causes dramatic, unexplained shifts in user counts and demographic reports between standard exploratory reports and pre-built standard reports, driving analysts mad trying to reconcile conflicting dashboards.
Privacy and Consent Quagmires: Relying on Google’s proprietary identity graph means trusting Google's internal matching algorithms, which are entirely opaque ("black box") and increasingly scrutinized under strict regulatory frameworks like the European Union's GDPR and the California Consumer Privacy Act (CCPA).
Interim Summary and Preview of Part 2
As we have examined in this first installment, Google Analytics is far from the infallible oracle of digital performance that its market dominance suggests. From the hidden distortions of data sampling and privacy thresholding to the steep cognitive and technical friction of GA4’s event-based architecture, and the persistent structural failure to resolve modern multi-device user journeys, the platform introduces significant hidden costs to organizations that adopt it without critical scrutiny.
However, the downsides do not end at data architecture and user attribution. In Part 2 of this expert analysis, we will delve into the darker operational and strategic consequences of using Google Analytics. We will explore:
The Privacy and Compliance Minefield: Navigating GDPR, Schrems II, IP anonymization controversies, and the legality of transferring European user data to US servers.
The Ecosystem Lock-In and Data Ownership Dilemma: How Google leverages analytics data to feed its advertising monopolies while restricting raw data access.
The Rise of Alternative Paradigms: Exploring privacy-first, server-side, and lightweight analytics alternatives (such as Matomo, Plausible, Piwik PRO, and Mixpanel) that prioritize data sovereignty, compliance, and user-centric clarity over corporate ecosystem lock-in.
Stay tuned as we continue dissecting the realities of modern web measurement and help you determine whether your analytics stack is truly serving your business—or serving Google.
It looks like your prompt got cut off or might be missing the main topic! Could you tell me what you would like to write or talk about, so I can help you out?