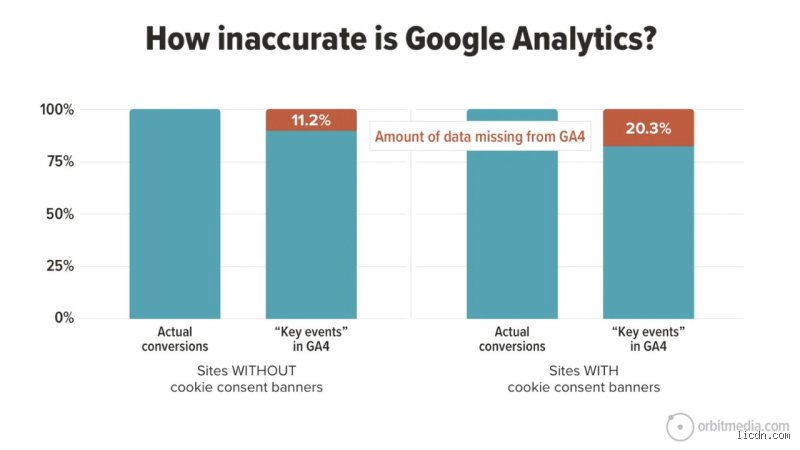
Let’s be honest with each other for a moment. When you open your Google Analytics dashboard—whether you are squinting at the legacy Universal Analytics data of yesteryear or navigating the modern, event-driven expanses of Google Analytics 4 (GA4)—what goes through your mind?
Do you look at those crisp, perfectly rounded visitor graphs, conversion rates down to two decimal places, and bounce rates calculated with algorithmic confidence, and feel a quiet sense of absolute certainty? Do you stand in front of stakeholders, C-suite executives, or clients, pointing your laser pointer at a traffic spike and declaring, "We received exactly 42,519 unique users on Tuesday because of our campaign"?
If so, we need to have a serious conversation.
Because the uncomfortable, industry-shaking truth that seasoned data analysts, privacy engineers, and seasoned digital marketers eventually learn is this: Google Analytics is not 100% accurate. In fact, expecting it to be is a dangerous delusion.
When you treat web analytics as an infallible oracle of truth rather than a probabilistic model of digital behavior, you risk making multimillion-dollar strategic blunders. You optimize for ghosts, misallocate ad spend, chase phantom conversions, and build marketing funnels on foundations made of shifting sand.
Throughout this deep-dive, expert-level exploration, we are going to pull back the curtain on how Google Analytics actually works under the hood. We will dismantle the comforting illusion of digital exactitude, examine the systemic flaws, technical barriers, and privacy walls that distort your data, and arm you with the critical mindset necessary to interpret your metrics intelligently. Let’s dive deep into the architecture of modern web measurement and find out why the numbers on your screen are almost certainly lying to you.
The Illusion of Exactitude: Why We Crave 100% Accuracy
Human psychology loves numbers. Numbers give us comfort. They impose order on chaos, transforming the messy, unpredictable behavior of millions of human beings browsing the web into clean, orderly spreadsheets and colorful pie charts.
When a business invests thousands—or millions—of dollars into digital marketing campaigns, SEO, and user experience design, leadership naturally demands accountability. They want a ledger. They want to know: If we put one dollar in, how many exact cents came out?
Google Analytics plays masterfully into this psychological craving. By presenting data with microscopic granularity—sessions lasting 01:42 minutes, engagement rates of 64.8%, and revenue tracked down to the fraction of a cent—it creates an intoxicating aura of precision. It feels like an accounting ledger.
However, unlike a bank account ledger where every single cent deposited or withdrawn must balance down to the penny due to strict double-entry bookkeeping, Google Analytics is fundamentally a sampling and estimation engine. It is an observational tool operating in an inherently hostile, fragmented, and privacy-obsessed digital ecosystem.
When you ask whether Google Analytics is 100% accurate, you are asking a question rooted in a category error. You are treating a sophisticated statistical approximation engine as if it were a physical cash register. To master analytics, you must first unlearn this misconception and embrace the reality of probabilistic digital measurement.
Architecture of Imperfection: How Data Breaks Before It Even Reaches GA4
To understand why your reports are riddled with discrepancies, you have to trace the perilous journey a single user interaction takes from a browser in London or New York all the way to Google’s data processing servers. At every single step of this journey, data is lost, altered, blocked, or misinterpreted.
Let's break down the primary culprits of data degradation.
1. The Client-Side Execution Barrier (Ad-Blockers and Privacy Extensions)
The vast majority of data collection in Google Analytics relies on client-side JavaScript tracking codes (such as gtag.js or Google Tag Manager snippets) executing inside the user's web browser.
Right out of the gate, you face a massive hurdle: your users do not want to be tracked.
Millions of internet users worldwide employ advanced ad-blockers (like uBlock Origin), privacy-focused browsers (like Brave, Mullvad, or Tor), and network-level content filters (like Pi-hole or corporate firewalls). What do these tools universally target? JavaScript tracking scripts belonging to major analytics and advertising platforms, with Google sitting right at the top of the target list.
If a visitor lands on your landing page with an aggressive ad-blocker active, the Google Analytics script may be completely blocked from loading, or its network requests to google-analytics.com may be intercepted and dropped.
The Result? That user is completely invisible to you. They bought your product, read your blog post, or clicked your call-to-action, yet as far as your GA4 dashboard is concerned, they never existed.
The Accuracy Impact: Depending on your audience demographic—tech-savvy audiences, B2B software developers, and privacy-conscious European consumers exhibit much higher ad-blocker adoption rates—you could be missing anywhere from 10% to over 40% of your actual traffic right off the bat.
2. Browser Restrictions, ITP, and Cookie Annihilation
Even if a user does not use a dedicated ad-blocker, modern web browsers have declared war on third-party cookies and severely curtailed the lifespan of first-party cookies.
Apple’s Safari browser, powered by its Intelligent Tracking Prevention (ITP) mechanisms, aggressively caps the storage duration of client-side JavaScript-set cookies. Browsers like Mozilla Firefox and Brave employ similar privacy protections, such as Enhanced Tracking Protection (ETP) and total cookie protection.
Consider what happens under these restrictions:
A user clicks your Google Ads link on Monday and visits your site. GA sets a client ID cookie.
Under ITP restrictions, if that user returns via a bookmark or direct link 8 days later, Safari may have wiped or truncated that cookie.
GA4 treats this returning visitor as a brand-new user, artificially inflating your user counts, distorting acquisition channels, and completely breaking multi-touch attribution models.
When your tracking relies on client-side cookies in a world dedicated to cookie eradication, your longitudinal data accuracy evaporates. You are trying to measure a moving target with a ruler made of melting ice.
3. Network Failures, JavaScript Errors, and Browser Crashes
We often assume that web pages load smoothly and execution occurs without a hitch. In reality, the web is a chaotic, friction-filled environment.
A user's mobile connection drops momentarily as they enter a subway tunnel just as they complete a purchase. The
purchaseevent payload fails to transmit to Google's servers.A poorly written third-party plugin on your WordPress or Shopify site throws a fatal JavaScript error higher up in the execution stack, halting script execution and preventing your Google Tag Manager container from firing altogether.
A user closes the browser tab a millisecond before the asynchronous tracking beacon finishes dispatching.
None of these lost events are logged. Google Analytics cannot report on data it never receives. Consequently, your conversion funnels suffer from silent data leakage—events that genuinely happened in the physical world but failed to register in the digital ledger.
The Thresholding and Sampling Illusion in GA4
Many marketers breathe a sigh of relief when they migrate to Google Analytics 4 because they are told: "GA4 uses event-based tracking and doesn't sample data the way Universal Analytics did!"
While it is true that standard standard reports in GA4 are largely calculated from un-sampled event streams for smaller to mid-sized properties, this comfort is largely illusory. As soon as your site scales, or as soon as you begin building complex, customized Explorations involving high-cardinality dimensions, you run headfirst into Data Sampling and Data Thresholding.
Understanding Google’s Invisible Red Pencil
When your queries exceed specific processing limits, Google Analytics quietly applies data sampling. Instead of processing every single event in your database, it analyzes a representative subset (say, 10% or 20%) and extrapolates the results across your entire traffic volume.
While statistical sampling can be remarkably accurate when executed correctly, it introduces sampling error.
If you look at niche conversion paths, low-volume landing pages, or high-value B2B lead generation forms, sampling variance can swing your metrics wildly from one day to the next, creating the illusion of sudden traffic drops or spikes where none actually occurred.
Furthermore, if your property deals with sensitive user data or lower traffic thresholds combined with user-ID features, Google applies Google Signals thresholding. If user counts drop below a privacy-preserving threshold in a specific reporting dimension, Google redacts rows of data entirely, replacing them with blank spaces or grouping them into an opaque "(other)" row.
How can an analytics tool be 100% accurate when parts of your data are actively hidden from you by automated privacy algorithms? The short answer: it cannot.
Bot Traffic: The Ghost in the Machine
Let's address the elephant in the room: who—or what—is actually visiting your website?
If you look at raw server logs alongside Google Analytics data for almost any public-facing website, you will notice an immediate, glaring discrepancy. Server logs show significantly higher traffic numbers than Google Analytics. Why? Because the modern internet is heavily populated by non-human actors.
Web crawlers, scrapers, malicious botnets, AI training scrapers, price-monitoring spiders, and automated vulnerability scanners flood every corner of the web 24/7/365.
While Google Analytics includes automated bot filtering routines designed to exclude known malicious or automated traffic signatures based on the IAB/CSI International Spiders and Bots list, no bot filter is 100% effective.
Sophisticated headless browsers (like Puppeteer or Selenium) can execute JavaScript, mimic human mouse movements, solve simple CAPTCHAs, and spoof user agents convincingly enough to bypass Google's automated detection filters.
When these sophisticated bots infiltrate your GA4 reports:
They inflate your user and session counts.
They distort your engagement rates by bouncing instantly or lingering unnaturally.
They pollute your conversion metrics if poorly configured goal events get triggered by automated form-submitting scripts.
Conversely, aggressive internal filtering or overly sensitive bot-exclusion rules can strip out genuine human users who happen to use unusual corporate VPNs or specialized browsers. Either way, your data accuracy is compromised from both ends—polluted by artificial traffic on one side and depleted by over-exclusion on the other.
The Attribution Quagmire: Who Deserves the Credit?
Perhaps the most glaring failure of accuracy in Google Analytics lies not in how many people visited, but in how they are credited when they convert.
Imagine a potential customer goes through the following journey:
Monday: Sees your brand via a display ad while reading a news site (View-through or click).
Wednesday: Searches for your specific product category on Google, clicks a paid search ad, and browses your catalog for 10 minutes before leaving.
Friday: Clicks a link in your weekly email newsletter and reads a blog post.
Sunday: Types your exact domain name directly into the browser URL bar and completes a $500 purchase.
In the default reporting setting of Google Analytics 4 (which relies on Data-Driven Attribution or Last Non-Direct Click depending on the configuration), how is this sale attributed?
Under traditional Last-Click models, 100% of the revenue is awarded to the Direct visit on Sunday.
Your paid search campaigns look like a waste of money, your display ads appear completely ineffective, and your email newsletter gets zero credit for nurturing the lead.
Even Google's advanced Data-Driven Attribution, while machine-learning-powered, relies heavily on algorithmic heuristics that attempt to guess probabilistic credit assignment across touchpoints that may have been partially blinded by cookie expiration or cross-device fragmentation.
When marketing attribution is fundamentally an educated guess, calling the resulting ROI metrics "100% accurate" is nothing short of corporate fiction.
Looking Ahead: The Crossroads of Measurement
As we stand here in 2026, the digital analytics landscape is undergoing its most radical transformation since the inception of the web. With cookie deprecation moving from delayed threat to hard reality, privacy regulations like GDPR and CCPA enforcing strict consent requirements, and artificial intelligence reshaping how users interact with content, the traditional paradigm of web tracking is fracturing.
In the second part of this expert analysis, we will take our investigation even further. We will explore:
The devastating impact of user consent banners and missing cookie-consent opt-ins on data integrity.
How Server-Side Tagging and Conversion APIs attempt to rescue lost data—and where they fall short.
Actionable frameworks for turning imperfect data into bulletproof business decisions.
The golden rule of modern analytics: How to stop obsessing over achieving an impossible 100% accuracy and start focusing on trend directional integrity.
Until then, take a hard look at your dashboards. Realize that those numbers are not absolute truths handed down from digital heaven—they are highly sophisticated, beautifully formatted, yet inherently flawed statistical estimates.
And once you accept that imperfection, you can finally start using Google Analytics the way it was truly meant to be used: not as a rigid ledger, but as a compass pointing you in the right strategic direction.
Bridging the Gap: What to Do When 100% Accuracy is a Myth
When looking at digital analytics, the dream of absolute precision is enticing. Yet, as we have unpacked, Google Analytics operates on a spectrum of approximation, modeling, and client-side friction.
As a result: treating your dashboard as an infallible ledger of truth is a dangerous trap. It is a compass, not a GPS tracker. But recognizing these inherent flaws does not mean you should throw your data out the window. Instead, it means changing how you interpret what you see.
Navigating the Imperfection
To make peace with Google Analytics, you must accept that directional trends matter far more than absolute numbers. If your report says traffic grew by thirty percent month-over-month, whether the exact growth was twenty-eight percent or thirty-two percent matters less than the undeniable upward momentum.
However, when high-stakes budget decisions hang in the balance, relying solely on surface-level metrics can lead you astray.
The Reality of Modern Measurement
Ironically, in an era where we track more digital footprints than ever before, our visibility is often cloudier than it was a decade ago. Privacy regulations, automated ad blockers, and strict browser cookie expirations mean that a chunk of your audience will always remain ghosts in the machine.
We must admit our limits: no analytics tool will ever capture every single human interaction with 100% fidelity.
In short, Google Analytics is an extraordinarily powerful tool, provided you respect its boundaries. Stop chasing the illusion of a flawless data score. Focus instead on consistent trends, validate your critical revenue milestones against backend financials, and remember that the best decisions use analytics as a guide—not a absolute dictator.