The narrative surrounding artificial intelligence leadership used to be simple. From the public debut of ChatGPT in late 2022 through the end of 2024, the race was framed as a straight sprint: OpenAI held the primary frontrunner status, while Google DeepMind, Anthropic, and open-source contenders scrambled to match its raw capabilities.
In 2026, that simple narrative has fractured. The single answer to "Who is winning the AI race?" no longer exists. Instead, the industry has splintered into distinct domain battlegrounds, where different technical paradigms, economic strategies, and architectural philosophies dominate. Determining who leads depends entirely on whether you evaluate market capitalization, enterprise revenue, agentic code execution, context handling, or hardware efficiency.
This multi-part series unpacks the architecture, state of the market, and capabilities of the leading frontier models. Part I analyzes the shift from parameter scale to test-time compute, evaluates the structural standings of the "Big Three" frontier labs, and details how specialization has replaced blanket dominance.
1. The Death of Single-Metric Leadership
For years, benchmarking frontier artificial intelligence followed a predictable pattern: measure MMLU (Massive Multitask Language Understanding), run basic coding evaluations like HumanEval, compare parameters, and declare a single king of the hill.
That paradigm has broken down due to two structural shifts in model design:
The Test-Time Compute Pivot: Scaling laws during pre-training have encountered diminishing returns per dollar spent. Frontier laboratories now allocate massive compute budgets to real-time inference—allowing models to reason, generate internal chains of thought, and execute multi-step verification cycles before outputting a response. A model with fewer base parameters can outperform a massive trillion-parameter dense model simply by running longer reasoning chains at runtime.
Task-Specific Convergence: At the basic conversational and knowledge retrieval level, top-tier models have reached functional parity for standard daily use. Evaluating whether GPT, Claude, or Gemini answers a history question better has become largely subjective. The real technical differentiation has migrated to high-stakes edge cases: execution of complex multi-file software engineering tasks, massive multimodal context reasoning, autonomous tool integration, and economic efficiency per token.
Consequently, the industry no longer features a single unified leaderboard. The race has transitioned into an oligopoly of hyper-specialized powerhouses.
2. The Big Three: Structural Standings & Strategic Imperatives
 ┌────────────────────────────────────────────────────────────────────────┐
 │ THE 2026 FRONTIER │
 ├───────────────────┬───────────────────────────┬────────────────────────┤
 │ LABORATORY │ CORE ARCHITECTURE │ STRATEGIC ADVANTAGE │
 ├───────────────────┼───────────────────────────┼────────────────────────┤
 │ OpenAI │ GPT Frontier Series │ Consumer Scale & │
 │ │ Reasoning Systems │ Distribution │
 ├───────────────────┼───────────────────────────┼────────────────────────┤
 │ Anthropic │ Claude Architecture & │ Enterprise API & │
 │ │ Deep Agentic Frameworks │ Coding Workflows │
 ├───────────────────┼───────────────────────────┼────────────────────────┤
 │
...[continuation from previous analysis]
The Enterprise Front: Trust, Safety, and Customization
While consumer metrics and flashy capability demos capture the public imagination, the true battleground for economic dominance has decisively shifted to the enterprise sector. Here, the criteria for leadership change dramatically. Raw parameter counts and creative flair take a backseat to determinism, data privacy, auditability, and integration depth.
In this arena, Anthropic has carved out an extraordinary niche that punches well above its relative size.
Meanwhile, Google Cloud leverages its sprawling infrastructure and Vertex AI ecosystem to anchor itself deeply into existing corporate software stacks. For businesses already reliant on Google Workspace or massive cloud data lakes, deploying Gemini models via managed pipelines represents the path of least resistance.
To map out how the major commercial strategies differ across the enterprise ecosystem, consider the following breakdown:
Open Source and the Global Challenger Dynamics
No discussion of the AI race is complete without evaluating the disruptive force of open-source and open-weight models, spearheaded aggressively by Meta with its Llama ecosystem.
In global developer hubs and alternative platforms like OpenRouter, open-weight and challenger models—including powerful offerings from emerging international players—frequently dominate token volume metrics.
Cost Efficiency: Running localized or fine-tuned open models dramatically reduces inference costs compared to paying premium tier subscription or API fees for closed frontier models.
Data Sovereignty: Enterprises and foreign governments with strict data residency laws refuse to transmit sensitive telemetry or proprietary documents to U.S.-hosted commercial servers, making local deployment of open-weight alternatives mandatory.
Furthermore, international competition—particularly from advanced labs in China—has compressed the innovation timeline.
Infrastructure, Energy, and the Compute Bottleneck
Ultimately, the ceiling of the AI race is defined not by algorithmic brilliance alone, but by physical and logistical constraints. Building, training, and serving the next generation of trillion-parameter models requires staggering amounts of capital, specialized silicon, and—most critically—electrical power.
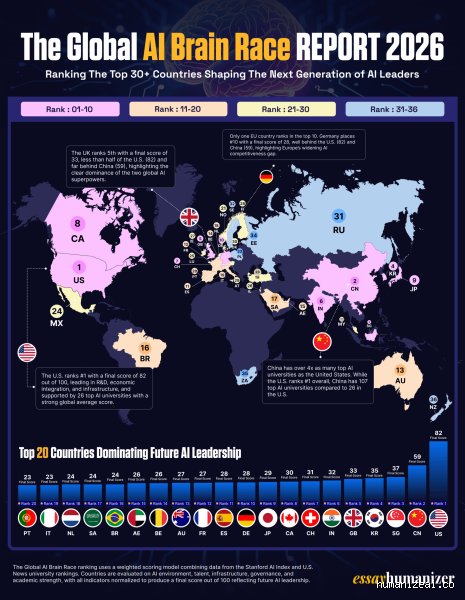
The United States and China continue to outpace all other regions in aggregate infrastructure investment, with U.S. tech giants projected to pour hundreds of billions of dollars into data center expansion. However, this expansion is increasingly colliding with real-world bottlenecks:
The Energy Wall: Modern AI data centers demand power footprints equivalent to mid-sized cities. Securing clean, uninterrupted baseload energy has forced tech conglomerates into unconventional partnerships with nuclear and renewable energy providers.
Local Opposition and Zoning: Community pushback against massive grid demands, water usage, and physical construction has delayed dozens of high-profile data center projects globally, proving that local consent is just as vital as microchip availability.
These physical realities favor players with deep pockets and diversified balance sheets. Companies like Google and Microsoft hold massive structural advantages in infrastructure, capable of absorbing capital expenditures that would bankrupt smaller startup labs.
The Verdict: Who is Winning the AI Race?
So, who is leading the AI race? The answer depends entirely on how you define the finish line.
If leadership is measured by brand resonance, consumer love, and rapid developer adoption, OpenAI holds the crown. They consistently capture the cultural narrative, pushing the envelope on agentic autonomy and setting the standard for how humans interact with machine intelligence.
If leadership is measured by underlying infrastructure, multi-modal breadth, and long-term computational staying power, Google commands the strongest structural moat.
If leadership is measured by enterprise trust, safety alignment, and precision in professional workflows, Anthropic punches far above its weight class, winning the loyalty of risk-averse corporate leaders.
And if leadership is measured by democratization and global reach, Meta’s open ecosystem is quietly powering the infrastructure of millions of downstream applications worldwide.
Ultimately, the AI race is transitioning from a high-stakes sprint for raw intelligence into a sprawling, multi-dimensional ecosystem. There will not be a single victor that swallows every use case. Instead, we are witnessing the birth of a diverse digital landscape where specialized superpowers dictate who wins each specific battle, ensuring that innovation continues to compound at a breathtaking pace.