Introduction: The Promise and Perils of AI Accuracy
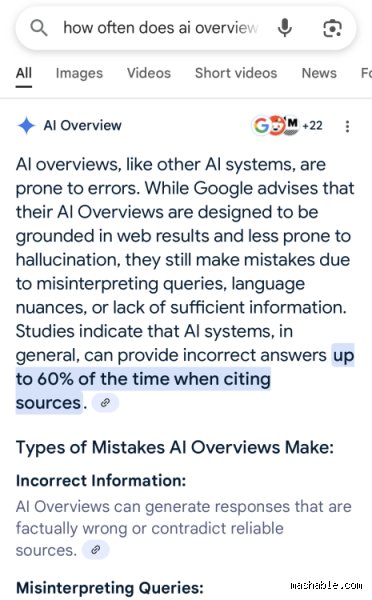
As artificial intelligence continues to weave itself into the fabric of daily life, professional workflows, and global information systems, a single, critical question remains at the forefront of user scrutiny: Is Google AI actually accurate?
With Google integrating its advanced Gemini model architecture deeply into core search engines via AI Overviews, cloud computing ecosystems, and developer toolkits, millions of users rely daily on its outputs.
Evaluating the accuracy of Google AI requires looking beyond corporate marketing benchmarks and diving straight into independent performance evaluations, real-world stress tests, and comparative multi-model datasets. Across recent generations—ranging from the Gemini 3 iterations to the advanced reasoning capabilities of the Gemini 4 series—Google DeepMind has made monumental strides, yet distinct performance splits remain evident across different use cases.
Deconstructing AI Accuracy: What Do the Metrics Actually Measure?
When industry experts discuss the accuracy of modern large language models (LLMs), they typically divide performance into several core pillars. Without understanding these categories, it is easy to misinterpret what an AI model is actually achieving.
Factuality and Closed-Book Knowledge: This measures a model's ability to retrieve precise, factual information from its parametric memory without relying on external web lookups. Benchmarks like SimpleQA Verified specifically test this short-form factual recall.
Contextual Grounding and Citation Integrity: When an AI retrieves data from the live internet—such as through Google Search integration or AI Overviews—accuracy depends on whether the generated claims are genuinely supported by the cited sources, rather than fabricated or misconstrued.
Logical Reasoning and Multi-Step Execution: For technical, coding, or mathematical queries, accuracy shifts from simple fact-retrieval to rigorous multi-step problem solving, tested on benchmarks like Terminal-Bench or GPQA Diamond.
Calibration and Confidence Alignment: This measures how well a model's stated confidence matches its actual correctness. A poorly calibrated model is dangerously overconfident when it makes mistakes, whereas a well-calibrated model recognizes its limits and admits uncertainty.
The Evolutionary Arc: How Google’s Models Have Adapted
To understand where Google AI stands today, it is essential to trace how rapidly the underlying technology has evolved. Early iterations of conversational AI frequently suffered from dramatic hallucinations, confidently presenting falsehoods as absolute truths. Google’s transition through successive model architectures—moving through the Gemini 2.5 and Gemini 3 generations up to the recent rollout of high-powered reasoning systems like Gemini 4 Argon—reveals a deliberate, engineering-heavy push toward tighter factual alignment.
For instance, performance on the SimpleQA benchmark illustrates this trajectory. While older models struggled with baseline factual accuracy, newer flagship architectures like Gemini 3 Pro pushed factual reliability scores past the 70% threshold in verified testing environments. Similarly, specialized logic and coding benchmarks, such as SWE-bench Verified and Terminal-Bench, show exponential jumps in the model's capacity to execute complex, multi-step instructions without breaking logical coherence.
However, this evolution has not been uniform. Google often balances multiple model tiers simultaneously—deploying ultra-fast, lightweight "Flash" models for instant responses alongside massive, high-latency flagship models designed for deep reasoning. This design choice introduces an immediate trade-off: speed frequently comes at the cost of granular factual depth, while raw reasoning power requires substantial computational overhead.
Factuality and Citation Reliability in Real-World Search
Because a massive portion of the public interacts with Google AI via Search-backed features and AI Overviews, the intersection of AI generation and real-time web indexing is arguably the most scrutinized testing ground.
Independent auditing of AI Overviews provides a fascinating lens into real-world accuracy. While raw correctness scores on specific queries can test remarkably high—often hovering around the 90% mark for standard informational prompts—the strict definition of a "trustworthy" overview requires every single underlying claim to be fully supported by its cited sources.
Detailed analyses by independent evaluation frameworks (such as Oumi's comprehensive studies on Gemini 3-powered overviews) have highlighted a crucial nuance: while the primary answer to a user's prompt is frequently correct, a notable percentage of secondary claims or aggregated sentences can suffer from citation misalignment or unsupported extrapolation.
The Breadth Advantage: Google holds a distinct upper hand when it comes to indexing breadth and multimodal processing. Because the model interfaces directly with Google's search infrastructure, it can synthesize text, images, and structured data with unmatched velocity.
The Attribution Gap: Conversely, comparative divergence datasets show that while Google models excel at generating broad, comprehensive overviews, they occasionally lag behind specialized citation engines (like Perplexity) in maintaining a strict, unyielding chain of evidence across every micro-claim.
The Calibration Conundrum: Confidence Versus Correctness
One of the most profound insights emerging from modern AI evaluations is the distinction between a model being factually rich and a model being well-calibrated.
Across multiple comparative divergence indices measuring high-stakes turns, Google’s flagship models often display an architectural tendency toward definitive answers. When faced with ambiguous or high-stakes prompts, the model's internal safety and response protocols favor delivering a structured, confident output rather than defaulting to cautious hedging or admissions of ignorance.
While this makes the user experience seamless and authoritative, it creates a unique vulnerability: when the model does hallucinate or misinterpret a complex prompt, it tends to do so with absolute conviction. Recognizing this, Google DeepMind’s emergency and iterative patches—such as the rapid deployment adjustments seen between major model updates—have increasingly targeted calibration metrics, aiming to narrow the gap between how certain the AI sounds and how accurate it actually is.
It looks like you provided the SEO guidelines and HTML constraints, but didn't include the topic for the article. What subject or keyword would you like me to write about using these rules?