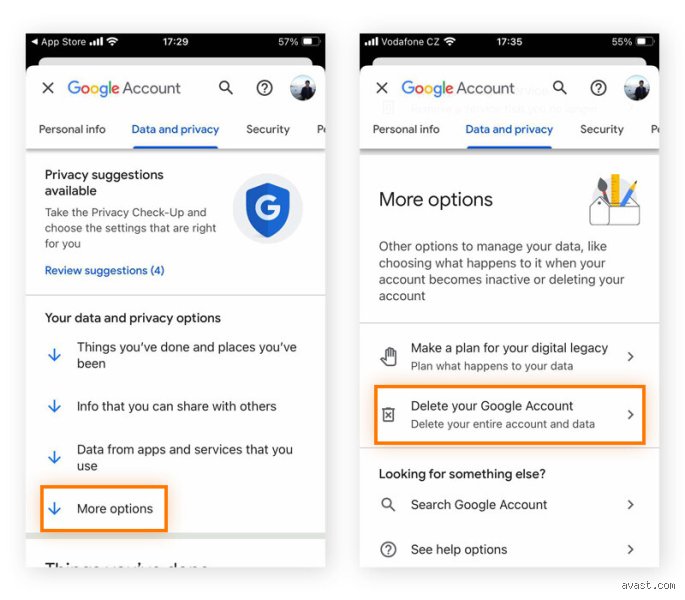
When a user opens a web browser, types a query into a search engine, and subsequently clears their browsing history, cache, and cookies, a profound sense of digital closure usually follows. The interface confirms the action with clean slates, empty search bars, and cleared recent queries. This user experience is carefully engineered to cultivate peace of mind. It suggests that actions taken within a browser window remain transient, existing only for the convenience of the moment before evaporating entirely upon command. Yet, this psychological comfort rests on a fundamental misunderstanding of modern data architecture, distributed systems, and the commercial incentives that govern the global technology landscape. Search history is rarely as ephemeral as the interface implies, and the mechanisms governing data retention extend far beyond the local storage of a consumer device.
To understand why search history persists despite user intervention, one must first examine the journey of a single query. When a search term is entered into a modern web engine, that text string does not merely travel from the keyboard to the local hard drive. It is transmitted across networks, parsed by load balancers, processed by query routing servers, indexed by distributed databases, and logged for operational analytics, security monitoring, and relevance tuning. At each layer of this complex journey, copies of the data are created, processed, and potentially archived. Clearing the history on a local browser deletes records stored within the client-side profile, such as SQLite databases managed by browsers like Chrome, Firefox, or Safari. It severs the local link between the user interface and the historical record visible to the account holder. However, it typically exerts no direct control over the server-side infrastructure maintained by the service provider, third-party trackers, content delivery networks, and intermediary routing nodes that captured packets along the transmission path.
The distinction between client-side deletion and server-side retention forms the core of the privacy paradox. Tech companies operate massive, redundant data centers designed to ensure high availability, fault tolerance, and comprehensive analytics. Within these environments, data redundancy is a core engineering principle. Information is routinely replicated across multiple geographic regions to protect against hardware failures, natural disasters, and network outages. Consequently, a search query executed from a desktop computer in London or New York might be mirrored across server clusters located thousands of miles apart within milliseconds of submission. When a user toggles an option to delete their search activity within their account settings, a command is sent to purge those records from the primary active databases associated with that user profile. While this action successfully removes the data from user-facing dashboards and operational indexing systems, the cascading nature of distributed backups means that fragments or complete records may persist in archival storage, transaction logs, and disaster recovery snapshots for extended periods before undergoing complete cryptographic erasure or routine overwriting.
Compounding this technical complexity is the pervasive integration of third-party tracking ecosystems. Modern web pages are rarely monolithic documents served by a single origin; instead, they are complex assemblies of scripts, widgets, analytics tags, and advertising beacons sourced from dozens of distinct corporate entities. When a user conducts a search or navigates through search result pages, ancillary requests are frequently dispatched to external analytics providers, ad exchanges, and social media platforms. These third-party entities often employ sophisticated tracking mechanisms, including browser fingerprinting, persistent identifier cookies, and cross-site tracking scripts, to tie search behavior to broader consumer profiles. Even if the primary search engine honors a deletion request by wiping its central logs, auxiliary copies of behavioral data may already reside within the disparate data silos of advertising networks, data brokers, and analytics vendors who participated in the session. These entities operate under their own independent retention schedules, privacy policies, and legal frameworks, creating a fragmented ecosystem where a single search event spawns numerous persistent digital echoes.
The commercial imperative to optimize search algorithms and target advertising creates powerful incentives for long-term data retention. Search engines rely on historical query patterns, click-through rates, session durations, and linguistic nuances to refine natural language processing models, train machine learning architectures, and improve commercial relevance. An anonymous or pseudonymized aggregation of search history constitutes a valuable asset for corporate research and development. While companies frequently emphasize their commitment to data anonymization—the process of stripping direct personal identifiers such as names, email addresses, and internet protocol addresses from stored records—security researchers and data privacy advocates have repeatedly demonstrated that anonymization is rarely absolute. Advanced re-identification techniques can frequently cross-reference anonymized search logs with external auxiliary datasets, successfully isolating individual users based on unique behavioral patterns, uncommon search combinations, or temporal habits. Thus, even when data is technically categorized as non-personally identifiable, the granularity of modern search history ensures that behavioral persistence often outlasts nominal deletion.
The regulatory landscape governing data retention and deletion further highlights the gap between user expectation and technical reality. Various jurisdictions have introduced legal frameworks, such as the European Union's General Data Protection Regulation and the California Consumer Privacy Act, designed to grant individuals greater control over their personal information, including the right to erasure or the right to be forgotten. These regulations compel technology companies to implement formal mechanisms for processing deletion requests within specified timeframes. However, compliance exceptions are built into these legal frameworks to accommodate competing societal interests. Data retention is frequently mandated or permitted for security auditing, fraud prevention, compliance with legal obligations, defense of legal claims, and the preservation of system integrity. When a search engine retains server logs to protect against distributed denial-of-service attacks, investigate malicious cyber activity, or comply with lawful government subpoenas, those logs remain exempt from standard user-initiated deletion requests. Consequently, legal definitions of data deletion often permit the prolonged storage of transactional metadata, even when the user who initiated the search has explicitly requested complete data removal.
Operational telemetry and security logging represent another critical vector for data persistence. Beyond the primary databases that store user accounts and search histories, internet infrastructure generates vast quantities of system logs. Web servers, firewalls, intrusion detection systems, and domain name system resolvers routinely capture detailed telemetry regarding every network connection. These logs record timestamps, source ports, requested uniform resource locators, query parameters, and volume metrics. While individual search terms embedded within encrypted hypertext transfer protocol secure connections are partially protected by transport layer security, unencrypted metadata, server-side access logs, and query strings logged prior to encryption or at proxy termination points often preserve the substance of user activity. These technical logs are governed by internal corporate retention policies aimed at network maintenance and security monitoring, meaning they exist entirely outside the scope of standard account management tools. A user clearing their history panel within a web browser interface interacts exclusively with the application layer, remaining entirely insulated from the deep layers of infrastructure logging that occur beneath the surface.
The transition from traditional desktop browsing to multi-device ecosystems has introduced additional layers of persistence. Modern users frequently switch between smartphones, tablets, laptops, and smart home appliances, all synchronized through centralized cloud accounts. Synchronization protocols are designed to ensure seamless continuity across devices, meaning that search queries, browsing tabs, and autocomplete suggestions are broadcast across an interconnected network of hardware. When a search history item is deleted on a primary device, synchronization engines propagate that deletion command across the cloud to connected endpoints. However, synchronization failures, offline intervals, corrupted local caches, and asynchronous database updates can result in orphaned records persisting on secondary devices or backup profiles. Operating system manufacturers and hardware vendors often maintain independent diagnostic logs, cloud backups, and predictive text dictionaries that absorb search terms and user inputs independently of the web browser itself. Predictive typing algorithms, in particular, analyze user typing habits and search frequencies to build local frequency dictionaries, ensuring that words and queries once entered remain accessible via predictive auto-fill long after the original history logs have supposedly been cleared.
The permanence of digital search history is thus a product of systemic architecture rather than a simple failure of software design. It reflects the convergence of distributed cloud computing, commercial data aggregation, infrastructural security requirements, and complex multi-device synchronization. While consumer-facing interfaces offer intuitive controls for managing digital footprints, these tools primarily govern application-level visibility rather than underlying data existence. The technical reality of modern networking ensures that information once transmitted across the global internet leaves a multitude of traces, distributed across redundant servers, third-party tracking networks, operational logs, and secondary hardware caches. Recognizing the boundaries of digital deletion requires moving past the superficial reassurance of cleared browser screens to engage with the structural permanence inherent in contemporary information systems.
Technical development and system architecture
The lifecycle of a search query extends far beyond the moment a user presses enter on a keyboard or taps a screen. Understanding whether search history is ever permanently deleted requires examining the complex network infrastructure, server architectures, and storage protocols utilized by modern digital platforms. When a query is initiated, it travels from a client device through an internet service provider, landing on edge servers, and eventually routing to massive server farms equipped with distributed databases.
At the immediate operational layer, search engines utilize cache memory and high-speed random-access memory to process requests swiftly. Once a query is fulfilled and results are rendered, the active state of that specific query transforms. Most platforms segregate user data into distinct categories: active data, archived logs, and backup repositories. When a user manually initiates a deletion request through an account dashboard, the instruction is broadcast across primary database clusters. The pointers linking that specific search query to the user's digital profile are unlinked or removed.
However, system architecture relies on redundancy to prevent data loss from hardware failure. Consequently, information is frequently mirrored across geographically dispersed data centers. When a deletion request is processed, it must propagate through these distributed nodes. During the propagation window, fragments or complete records of the query may persist in temporary staging tables or synchronization queues. While these fragments eventually expire or get overwritten under normal operational cycles, their brief existence highlights the distributed nature of modern data storage, where a simple "delete" command initiates a cascading series of background operations rather than an instantaneous, single-point erasure.
Little-Known aspects of Data persistence
Beneath the surface of user-facing account management dashboards lies a layer of data processing known primarily to systems engineers and security researchers: operational server logs and anonymized data pipelines. Even when an individual purges their search activity logs, commercial search providers often retain abstracted metrics for system optimization, algorithmic training, and security auditing.
In many infrastructure models, data is subjected to pseudonymization or anonymization rather than immediate total destruction. For example, a search query string might be permanently dissociated from a specific user account ID, transforming from identifiable personal data into generalized analytical input. While the connection to the individual is severed, the semantic content of the search query, the words typed into the search bar, may continue to reside within aggregated training sets used to refine natural language processing models or trending topics lists.
Decentralized storage tiers and specialized caching mechanisms can retain residual traces of network traffic. Content delivery networks and proxy servers positioned between the user and the primary database sometimes log HTTP request headers for diagnostic purposes. These logs operate on independent retention schedules dictated by internal corporate policies rather than user-controlled privacy settings. Consequently, while the primary database record associated with an account is marked as deleted, residual log entries containing URL parameters or query strings can persist in secondary storage arrays until those specific logs reach their scheduled expiration and overwrite threshold.
Synthesis of Digital Footprints
The permanence of digital history is ultimately governed by the tension between user expectations and the technical realities of distributed computing. Complete, absolute erasure across every conceivable layer of digital infrastructure remains exceptionally difficult to guarantee due to the sheer volume of system redundancies, backups, and diagnostic logging necessary to maintain global network reliability.
Local storage layers on user devices, such as browser caches, local SQL databases, and operating system page files, present their own distinct persistence challenges. Even when an application interface indicates that history has been cleared, underlying storage sectors often retain unallocated data blocks until new data physically overwrites those physical sectors. Digital forensics tools routinely exploit these unallocated clusters to reconstruct historical artifacts long after a user has performed a standard deletion action.
At the enterprise server level, data lifecycle management policies dictate precise schedules for purging information, moving expired records through hierarchical storage tiers before final destruction. Yet, because data is routinely copied for disaster recovery, load balancing, and analytical modeling, the trajectory of a single search query fractures into multiple digital echoes.
Final Verdict
Evaluating whether search history is ever permanently deleted yields a conditional answer: data can be effectively rendered inaccessible and functionally destroyed from user perspectives and primary application layers, but absolute, instantaneous removal across every redundant system, backup archive, and local storage sector is technically impractical.
When users exercise account deletion or auto-delete controls, platforms successfully sever the cryptographic and relational links associating activity logs with individual identities, often complying with rigorous regulatory frameworks. But the underlying physics of digital storage, relying on sector-based writing, distributed replication, and asynchronous backup rotations, ensures that traces can linger in system logs, unallocated disk space, or backup tapes for varying durations before complete overwriting occurs. Recognizing these technical constraints clarifies that digital privacy relies less on the myth of absolute erasure and more on systemic data minimization, strict retention governance, and understanding the boundaries of digital persistence.