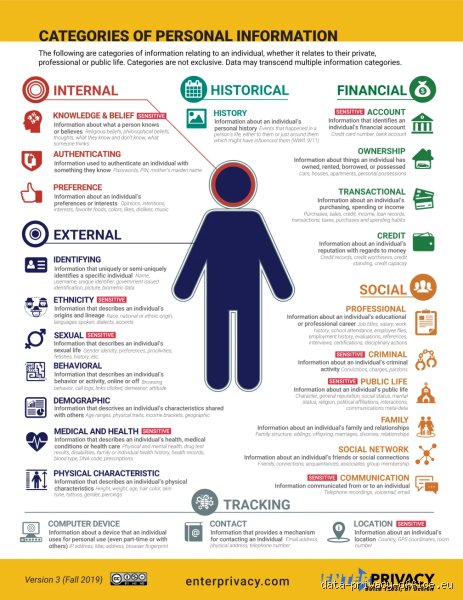
Understanding the core framework of personal Data under European Regulation
When examining the scope of regulated information, compliance professionals must look beyond obvious identifiers. A single piece of data may seem entirely neutral in isolation, yet it transforms into protected material the moment it links back to a specific human being. Understanding these nuances requires a systematic examination of the primary categories established by European lawmakers, starting with standard personal data and expanding into heightened tiers of regulatory scrutiny.
Standard personal Data versus direct identifiers
Standard personal data forms the baseline of the regulatory framework. Direct identifiers include names, home addresses, email addresses, telephone numbers, identity card numbers, and specific account login details. When an organisation collects a customer database containing names and contact details, every single entry falls squarely under the jurisdiction of the regulation.
However, the legal definition extends significantly further into indirect identifiers. Indirect identifiers consist of pieces of information that do not name a person immediately but can point toward them when combined with other elements. Examples include device fingerprinting data, Internet Protocol addresses, cookie identifiers, radio frequency identification tags, and vehicle registration numbers. A corporate entity processing web traffic logs containing Internet Protocol addresses is processing personal data, because telecommunications providers or internet service companies can correlate those network addresses with physical subscribers.
Special Categories of sensitive information
Certain types of information carry inherent risks to fundamental human rights and freedoms. Recognising this vulnerability, the legislation establishes a heightened tier known as special categories of personal data. Processing these sensitive types of information is prohibited by default unless specific, stringent legal exemptions apply.
The legally designated special categories encompass information revealing:
Racial or ethnic origin
Political opinions
Religious or philosophical beliefs
Trade union membership
Genetic data
Biometric data processed uniquely to identify a natural person
Data concerning health
Data concerning a natural person's sex life or sexual orientation
For instance, a company operating a workplace wellness portal that tracks employee cholesterol levels or physical disabilities handles health data. Similarly, a technology platform implementing facial recognition software captures biometric data. Both scenarios demand exceptional security measures and explicit consent or another robust statutory justification under Article 9.
Criminal convictions and related offences
While listed separately from the primary special categories, information relating to criminal convictions, offences, and related security measures commands a distinct, rigorous status. Under the framework, organisations generally cannot process this data unless official public authority controls it, or member state law authorizes the processing under strict safeguards. Private corporations face severe restrictions when running background checks or processing judicial history, ensuring that criminal records remain shielded from commercial exploitation.
Pseudonymised Data and its regulatory standing
Organisations frequently implement technical safeguards to obscure identities, leading to distinct classifications regarding data states. Pseudonymisation involves processing personal data in such a manner that the data can no longer be attributed to a specific human subject without the use of additional information. This additional information—such as a master decryption key or a lookup table—must be kept separately and subjected to technical and organisational security measures.
A critical legal distinction separates pseudonymised data from completely anonymous data. Pseudonymised information remains fully regulated personal data. Because a separate key exists that can reverse the process and re-identify the individual, the regulatory obligations continue to apply. Pseudonymisation serves as an invaluable risk-reduction tool and a mandatory security safeguard, but it does not exempt a database from compliance mandates.
Truly anonymous Data outside the regulatory scope
In direct contrast to pseudonymised records, genuinely anonymised data falls entirely outside the scope of European data protection rules. Anonymisation must be irreversible. If an organisation strips all identifying elements permanently, removes indirect correlations, and ensures that re-identification using reasonable technical means is impossible, the resulting dataset ceases to be personal data.
Evaluating whether data is truly anonymous requires assessing modern technological capabilities, computing power, and external datasets. If a dataset can be reverse-engineered or matched against public registries to expose individuals, it remains personal data regardless of an organisation's labeling practices.
Would you like to explore the specific compliance requirements and legal exemptions governing Special Categories of Data in the next section?
Semantic variants refer to different ways of expressing the same underlying meaning or concept using alternative words, phrases, or sentence structures while preserving the original intent. In natural language processing and communication, understanding semantic variants helps systems and humans recognize that distinct expressions share identical or closely related meanings.
Key expressions and concepts
Synonymy: Words with different spellings and sounds that have the same or very similar meanings in a given context (e.g., car and automobile).
Paraphrasing: Restating a phrase or entire sentence in other words to clarify meaning or improve readability without altering the core message.
Lexical Variation: Using different vocabulary choices across dialects, regions, or social contexts to describe the exact same object or action (e.g., sneakers versus trainers).
Syntactic Alternation: Changing the grammatical structure of a sentence while keeping the semantic content intact (e.g., active voice to passive voice).
Polysemy and Context: Words that have multiple meanings depending on the surrounding text, requiring contextual analysis to determine the correct semantic variant.
Semantic Similarity: A mathematical or conceptual measure of how close two pieces of text are in meaning